[작성자:] Saturn

  • Kim Kyung-il on AI: Why Verification and Collaboration Matter More Than Speed

    Kim Kyung-il on AI: Why Verification and Collaboration Matter More Than Speed

    Work gets faster when AI drafts content and summarizes materials for us. But does doing more at that faster pace always produce better results? If incorrect information slips in, we may also release more work without checking it.

    In a STUDIO LOLA interview, cognitive psychologist Professor Kim Kyung-il says AI has made his work easier but also made him more vigilant. The concern is not just the possibility of being replaced. He also worries about trusting incorrect AI content or citing it without verification. The video’s central concern is not that we should use AI less. Instead, it can be understood as a call to rebalance the time spent generating content and exercising judgment.

    The More Convenient AI Becomes, the More We Must Distinguish Finding from Verifying

    Finding the information we wanted used to take considerable time. It was easy to see a hard-won answer as an achievement. Now a question immediately produces fluent sentences and organized lists. But getting an answer and knowing it is correct are different things.

    Kim is particularly wary of readily trusting AI’s plausible answers. Fluent writing can make information feel as though someone has already reviewed it. Copy an AI explanation into a report or teaching materials, and you pass along unverified claims under your own name.
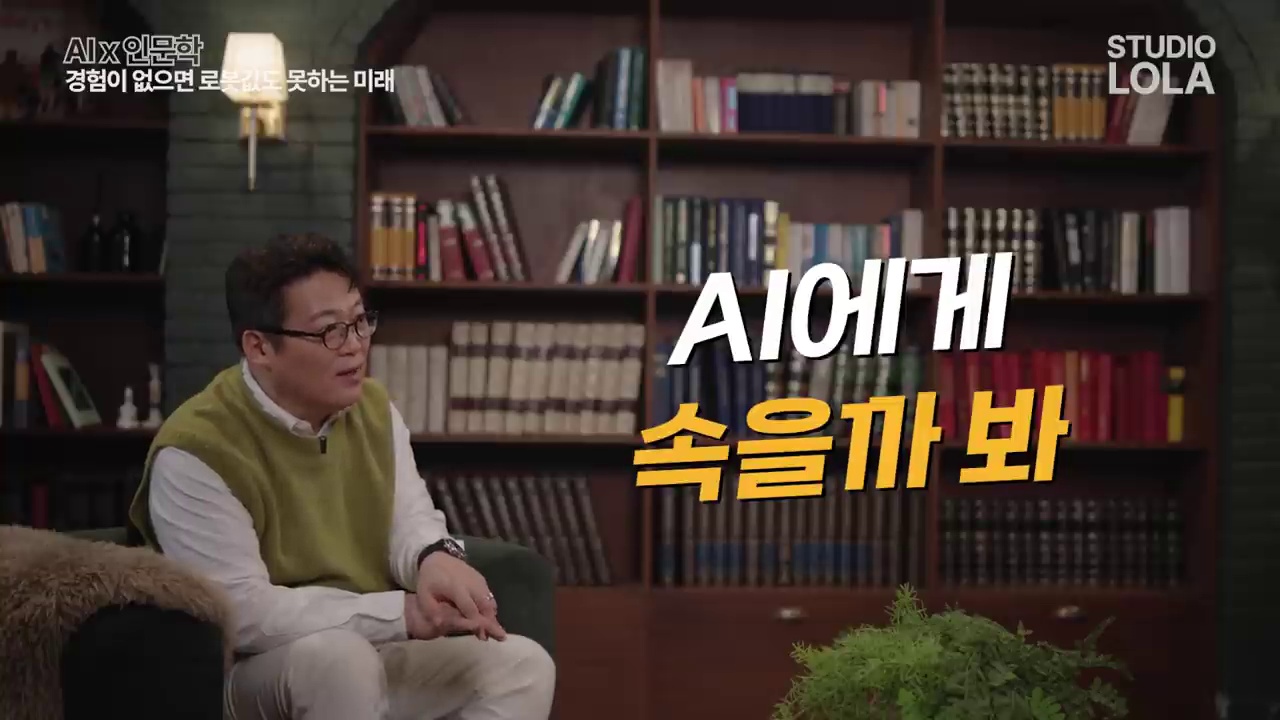
    Professor Kim Kyung-il explains the risk of taking AI answers at face value
    Source: STUDIO LOLA, original video at 06:00. Frame quoted to illustrate the discussion.

    The video also presents a strong view that language model hallucinations will persist. We need not interpret this as permanent proof of the limits of future technology. The practical message is clearer: Check the answers from today’s AI on the assumption that they may contain errors.

    Do Not Fill All the Time You Save with More Work

    Kim says agentic AI has helped him handle more work faster. Yet he remains vigilant because he feels he may also be making more mistakes. This is a personal impression, not a productivity statistic or experimental finding that applies to everyone.

    What follows is the important point. Rather than making speed the sole goal, he says we need quiet time afterward to check, reflect, and verify.

    Applying this perspective changes how we evaluate AI use at work. We should consider not just drafting speed, but also the process of finding errors, correcting them, and finalizing the work. Generation may be faster, but fact-checking and rework can still take considerable time. Perceived speed and actual performance may therefore differ.

    The following practical workflow draws on the concerns raised in the interview. It is not a formula or measurement scale validated in the video. It is a sequence for making sure verification does not get overlooked.

    1. Generate: Give AI the purpose, audience, and scope of materials, then request a draft.
    2. Separate: Label factual claims, opinions, estimates, and proposed actions separately.
    3. Verify: Check figures, quotations, laws, and proper names against the original sources.
    4. Judge: Remove statements with insufficient support or explicitly state the uncertainty.
    5. Approve: Have the person responsible perform a final check before external delivery, publication, or execution.

    Asking AI for another review can help. But agreement from another answer cannot replace checking the original source. What matters is not the number of reviews, but which evidence and actual results you checked against.

    Do Not Reduce a Profession to a Single Digital Task

    The interview uses radiology to show that a profession involves more than its most visible specialist task. Beyond interpreting images, the work includes persuading patients, coordinating with other medical professionals, securing organizational resources, and taking responsibility when problems arise.

    This discussion does not treat the video’s claims about salary changes or task proportions as verified statistics. Instead, it offers a way to understand professions: distinguish an easily automated task from the relationships, circumstances, and responsibilities surrounding it.

    Training professionals’ work can be divided in a similar way. AI can help write announcements and summarize surveys. But persuading reluctant employees, coordinating training schedules with operational departments, and reconciling different stakeholders’ needs remain separate tasks.

    This does not guarantee that any profession will remain safe forever. It means we should not judge automation potential by job titles or only the most conspicuous technical tasks.

    Collaboration Skills Come from Working Together, Not Just Knowing the Theory

    Kim also emphasizes understanding people unlike ourselves and gaining experience working with them. He cautions against giving up on collaboration simply because people differ in age, gender, or cultural background.
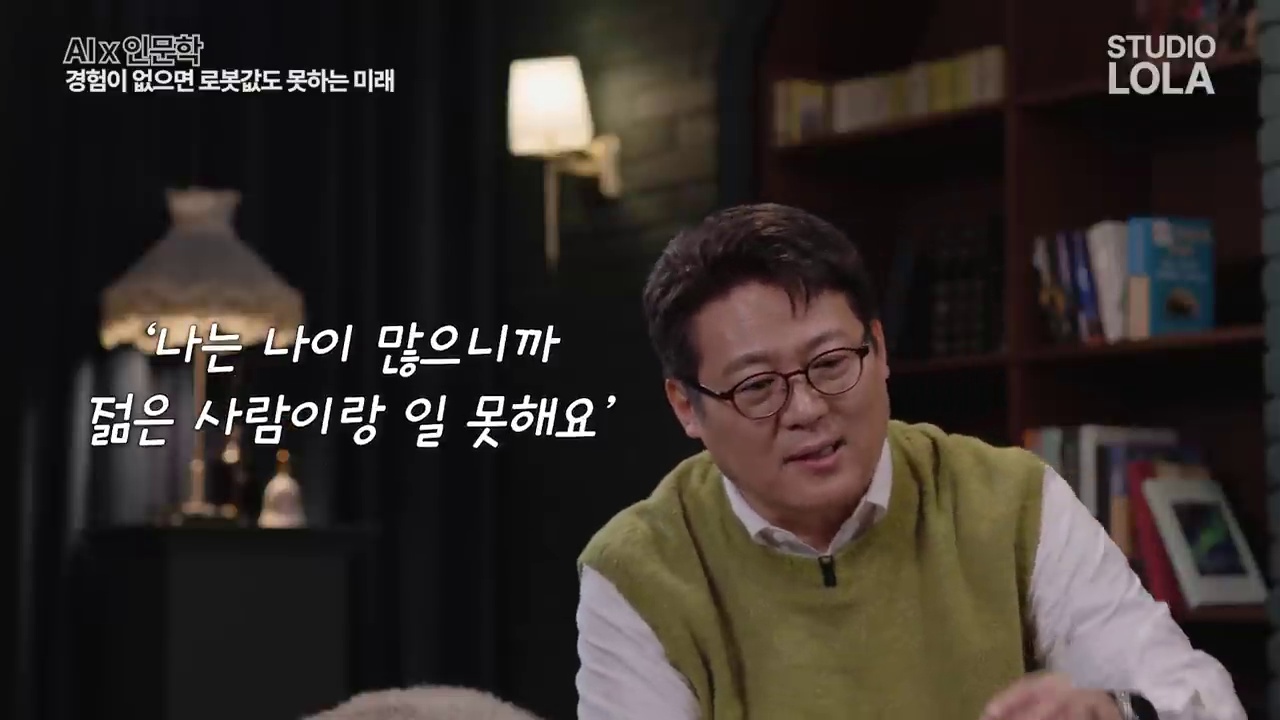
    Professor Kim Kyung-il emphasizes experience collaborating with people different from oneself
    Source: STUDIO LOLA, original video at 09:20. Frame quoted to illustrate the discussion.

    Knowing that empathy matters is different from actually reaching agreement with someone. We learn by hearing why someone interprets the same proposal differently, changing our explanations, and repairing relationships after conflict.

    Talking only to AI makes feedback easy to obtain, but it does not eliminate real people’s objections or hesitation. Developing collaboration skills requires keeping opportunities to work with people.

    • Explain a draft to a colleague in a different role and listen to what they find unclear.
    • When opinions clash, first identify the conditions the other person wants to preserve and the risks they fear.
    • Try explaining the same content separately to a manager, a practitioner, and a user.
    • After finishing, reflect not only on the result but also on what you missed during coordination.

    These activities need not be seen as the opposite of using AI. Use AI to organize materials and draft content. Then you can spend the time saved meeting people and understanding context.

    Studying the Humanities in the AI Era Is Not a Retreat from Reality

    In the interview, the humanities are not decorative knowledge detached from a changing world. Kim explains their role through the growing need to understand people at historical turning points.
    Professor Kim Kyung-il discusses the connection between cognitive psychology and studying the humanities
    Source: STUDIO LOLA, original video at 05:10. Frame quoted to illustrate the discussion.

    Learning AI’s capabilities can go hand in hand with learning about people. That means understanding what technology can do while considering who receives its output and the circumstances in which they use it.

    For example, an automatically written notice may be grammatically correct yet unhelpful to users. A survey summary may look accurate while overlooking conditions on the ground. That is why skill with tools needs judgment about people and situations.

    Five Things to Check in the Work You Create with AI Today

    The phrase ‘people becoming less intelligent’ in the video’s title should not automatically be read as a research finding about cognitive decline. The interview poses a practical question: as tools become more convenient, are we unthinkingly handing over our judgment too?

    Before releasing your next piece of work, ask five questions.

    1. Can I distinguish facts I checked myself from explanations supplied by AI?
    2. Did I actually open the sources I cited and check their context?
    3. Have I considered who would be affected if this result were wrong?
    4. Did I spend some of the time AI saved on checking and reflection?
    5. Did I revise anything after listening to actual users or colleagues?

    Competitiveness in the AI era cannot be explained solely by how quickly we produce more output. Kim’s interview shifts attention toward checking quickly generated answers and gaining experience working with people unlike ourselves. The starting point is to enjoy the convenience without handing over judgment and responsibility.

    Related Reading

    FAQ

    Does heavy AI use necessarily weaken thinking skills?

    This interview alone cannot establish that causal relationship. The central point is not how much AI we use. It is to be careful about trusting AI explanations without checking them and surrendering our judgment.

    How should I verify AI answers?

    Separate statements that require checking, such as figures, quotations, and laws, then compare them against original sources and actual materials. Remove unsupported claims or mark the uncertainty. Do not consider verification complete merely because another AI gave the same answer.

    Why does collaboration experience matter in the AI era?

    Work involves not only processing information but also persuading people, coordinating interests, and taking responsibility for outcomes. The interview emphasizes that these abilities develop through experience working with different people.

    How should I use the time AI saves?

    Rather than spending it all on more work, reserve some for reviewing output, checking original sources, reflecting, and listening to actual users and colleagues. Instead of a fixed time ratio, let the work’s risks and required level of verification guide you.

    References

    The images are video frames quoted to explain and critique the interview. The speaker’s views and personal impressions are distinguished from general research findings. The practical checklist was adapted from the concerns raised in the interview.
    Original Korean article

  • CrewAI Beginner’s Guide: Design Multi-Agent Work with Agent, Task, and Crew

    CrewAI Beginner’s Guide: Design Multi-Agent Work with Agent, Task, and Crew

    How does asking AI to write a report in one request differ from assigning research, analysis, and writing separately? Adding more agents does not automatically improve the result. Division of labor matters only when you define who uses which tools, what they produce, and what they hand off.

    CampusX’s CrewAI masterclass is an extensive introductory course covering agent fundamentals through multi-agent projects. Drawing on the course and its public examples, this guide explains how to distinguish Agent, Task, and Crew, the basic structure for producing reports and blogs, and how to expand into market research projects. Installation steps are compared with current official documentation to distinguish them from the file structure shown in the video.

    What does CrewAI help organize?

    CrewAI is a Python-based framework for configuring multiple AI agents to share work by role. It is not a model itself. It is closer to an execution system connecting agents that use models and tools to complete tasks.

    You could put all research, judgment, and writing instructions into one large prompt. As work becomes more complex, however, missing evidence and the role output requiring revision become harder to identify. CrewAI lets you separate roles and tasks and specify execution order and the context to pass along.

    Not every job needs multiple agents. One model call may be simpler for a basic summary or a short sentence edit. Consider dividing work when the tools, information, and judgment criteria genuinely differ between roles.

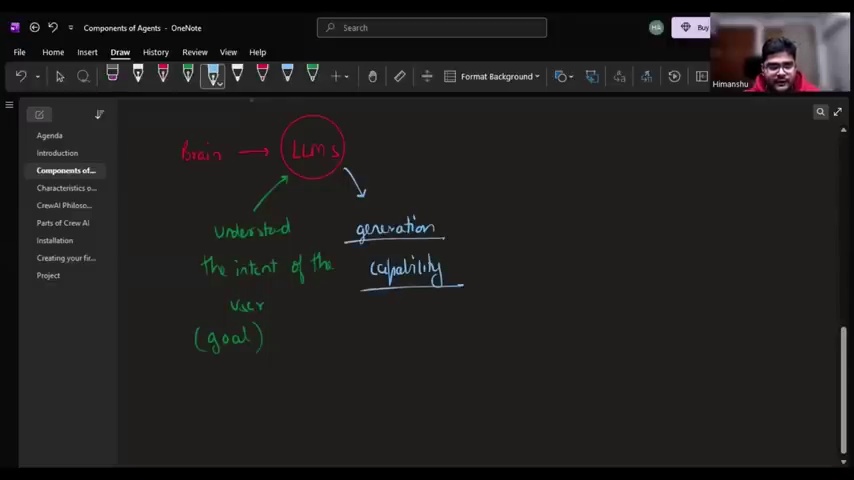
    CampusX lecture explaining the LLM's role in an agent configuration
    Source: CampusX, source video at 31:40. Frame quoted to illustrate the discussion.

    Three concepts beginners should distinguish first: Agent, Task, and Crew

    Agent means ‘who does the work’

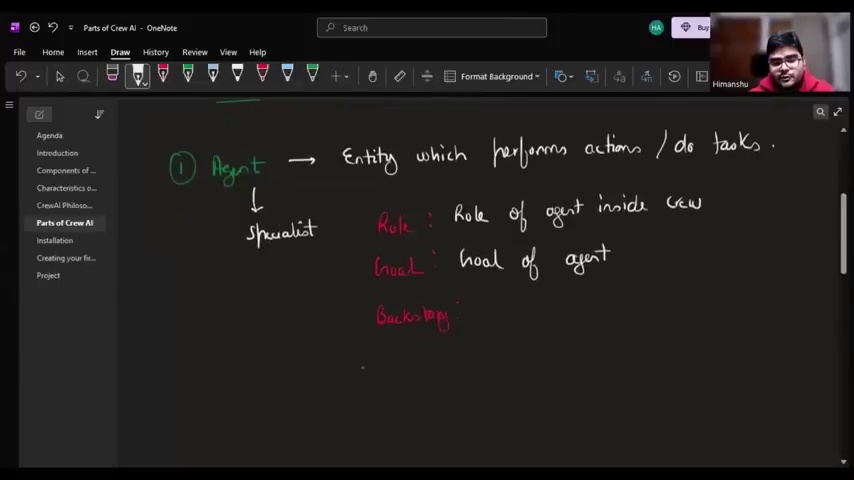
    An Agent defines a role, goal, backstory, and other attributes. You can also specify its model and tools as needed. A researcher might focus on search and source collection. A writer might focus on explanations and structure suited to the audience.

    Describing expert experience in a backstory is a setting that guides the role. It does not mean an expert with that experience reviewed the work, nor does it guarantee factual results.

    Task means ‘what must be completed’

    A Task includes a description and an expected_output. It can also connect the assigned agent, previous task results to consult, and output files.

    Specific research scope, reference dates, required items, sources, and uncertainties support later review better than a request to ‘research thoroughly.’ Defining expected output clarifies completion criteria. It does not guarantee that the model will meet them.

    Crew means ‘how the work runs together’

    A Crew groups agents and Tasks and determines how they execute. Start with sequential execution when the order is clear. A hierarchical setup coordinated by a manager role is another option, but adds separate judgment and delegation steps.

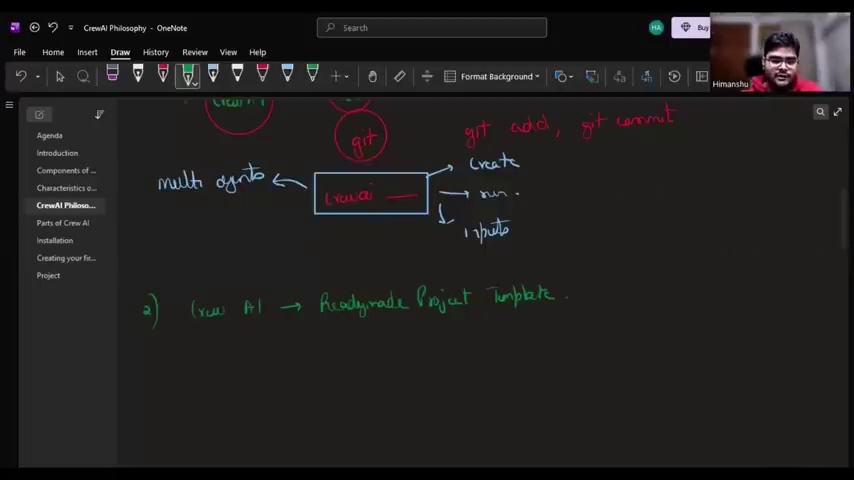
    Lecture screen explaining Crew as a multi-agent execution system
    Source: CampusX, source video at 80:00. Frame quoted to illustrate the discussion.

    For beginners, rather than creating many job titles, it helps to first sketch the connections on paper: input → responsible role → deliverable → next task.

    First example: separate report writing from blog writing

    The public repository’s research_and_blog_crew uses two roles. A report-writing agent organizes information on a topic, and a blog-writing agent turns it into readable prose.

    The YAML settings target about 2,000 words for the report and about 500 words for the blog. These are requested lengths, not evidence of automatic length or content verification. The Python code uses Process.sequential to execute the work and configures the blog output to be saved to blogs/blog.md.

    One detail is easy to miss. The agents in this basic example have no web search tools connected. Asking for ‘the latest facts’ in a prompt does not mean current sources were actually collected from the web. For work requiring search, configure tools and access permissions separately.

    Saving text to a file is also different from completing public publication. The output file setting in this example does not itself publish to WordPress. If external publication is needed, design separate review, approval, and publishing steps.

    Lecture screen explaining a CrewAI Agent's role and goal
    Source: CampusX, source video at 96:40. Frame quoted to illustrate the discussion.

    To apply this example at work, strengthen the deliverable requirements as follows. These are practical suggestions, not settings reproduced verbatim from the course code.

    • In the report, distinguish verified facts, original sources, reference dates, and items not yet verified.
    • The blog writer must not arbitrarily add figures or examples absent from the report.
    • In the final review, check quotations, links, and whether claims match their supporting evidence.
    • Keep external publishing permissions separate from draft generation, and use them only after approval.

    Expanded example: divide market research into five roles

    The public repository’s market_research_crew demonstrates a more complex division of labor.

    1. Market researcher: Researches market size, growth trends, and the industry environment.
    2. Competitive intelligence analyst: Examines competitors, alternatives, and opportunities for differentiation.
    3. Customer insights specialist: Organizes customer segments’ problems, needs, and purchasing hypotheses.
    4. Product strategist: Proposes feature priorities and development direction based on the preceding findings.
    5. Business analyst: Integrates the research findings into a business report.

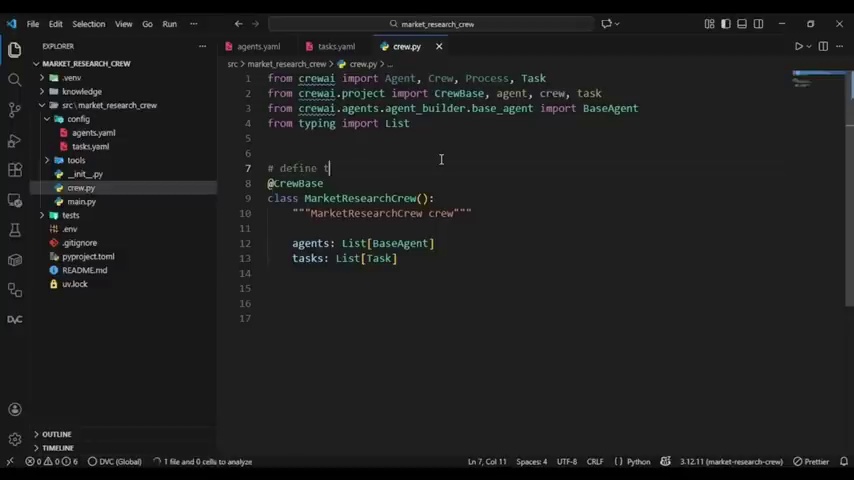
    In the final exercise, the video inputs a product idea: a tool that summarizes YouTube videos and posts to multiple social platforms. It then generates and examines a related business report. The result is a market and business viability analysis of that product. It is not a working service that summarizes videos or posts to social media.

    The code connects later Tasks to earlier results through context. For example, the product strategy Task receives market, competitor, and customer research findings. The final business analysis Task brings several results together and saves them to reports/report.md.

    Hands-on exercise screen showing Python Crew code for the market research project
    Source: CampusX, source video at 191:40. Frame quoted to illustrate the discussion.

    This example connects search and webpage collection tools. Unlike the basic report and blog example, its configuration lets agents retrieve external information. However, obtaining search results does not automatically guarantee the validity of market figures or business forecasts.

    In particular, an AI-generated customer persona is not an actual customer interview. Separate observations confirmed through research from hypotheses generated by the model. Another agent summarizing the same model’s output does not constitute independent verification either.

    Before installation: today’s default structure differs from the course’s YAML structure

    The course examples use crew.py, config/agents.yaml, config/tasks.yaml to configure roles and tasks. However, the official installation documentation checked while preparing this guide says default projects are generated with a JSON-centered structure. Agent definitions go in agents/*.jsonc, while Task and Crew settings go in crew.jsonc.

    A different file structure in your current CLI does not necessarily mean installation failed. To learn with the video’s Python/YAML structure, check the officially documented --classic option.

    For an environment with uv available, the creation procedure is as follows. These installation commands are learning examples based on official documentation. Check your environment against the CrewAI version and model provider settings you plan to use.

    uv tool install crewai
    crewai create crew research_and_blog --classic
    cd research_and_blog
    

    Read the generated project’s instructions and configure your chosen model and tools. Manage secrets such as API keys through environment variables or .env, and do not commit them to a repository. Once configured, install dependencies and run the project from its root directory.

    crewai install
    crewai run
    

    Also distinguish a free course from execution costs. Even if viewing the course is free, your chosen model, search API, and external services may incur charges or usage limits. Check key issuance, billing, and request limits before learning.

    Sequential execution, hierarchical execution, and Flow are not equivalent options

    Sequential execution follows a predefined Task order. It is easy to understand and trace when dependencies are clear, such as research before writing.

    In hierarchical execution, a manager role coordinates the work. Consider it when delegation must adapt to circumstances. However, the manager’s judgments also involve model calls and possible errors. More agents or an added manager do not themselves prove better performance.

    Flow is a separate concept for connecting processing steps, state, and conditional branches through code. For example, you could validate input, run a research Crew, and route insufficient findings to a supplementary research path. This illustrates a practical application of official concepts. It does not mean the course’s market research project implements such branching.

    An approachable starting sequence is a small sequential Crew → deliverable verification → necessary branching . Clear rules can be handled in ordinary code, rather than assigning agents work that needs no dynamic judgment.

    Define operating criteria before deciding the number of agents

    Using multi-agent systems at work requires operating conditions as well as role names. Check the following when adapting an introductory example to real work.

    • Tools and permissions: Specify which actions are permitted: reading, searching, saving files, and external transmission.
    • Handoff information: Define the evidence, sources, and unverified items that the next Task must receive.
    • Verification: Check required fields, formats, and supporting references separately. Passing a format check does not make the facts correct.
    • Retries and cost: Instead of unlimited loops, define stopping and retry criteria after failure and set cost limits.
    • Publication approval: Separate automatic generation and saving from customer delivery and public publication.

    These boundaries matter more than labeling a role as an expert. Track which Task went wrong and prevent unverified results from passing unchanged into the next stage.

    A beginner’s first goal is to explain a small Crew

    When learning CrewAI, start with a small, two-role task rather than a large organizational chart. With the same input, check what information it receives, where it might fail, and what it leaves as the final deliverable.

    The CampusX course helps connect agent fundamentals and role division to actual project structures. However, an example running successfully differs from achieving quality ready for immediate use at work. This guide compares the course, public code, and official documentation. It does not claim that the example Crew was run separately to reproduce the same deliverables.

    Getting started with CrewAI is not about memorizing tool names. The key is to clarify who does what, on what evidence, and who checks the result.

    Related reading

    FAQ

    Do I need to know Python to use CrewAI?

    This course covers both Python code and YAML settings. Understanding agent concepts differs from modifying and running examples. Learning code structure and the basics of packages and environment variables helps.

    Why does the generated project’s file structure differ from the course?

    The current official installation documentation presents JSON-centered projects as the default. To follow the video’s Python/YAML structure, check the crewai create crew project-name --classic option. Also consult the documentation matching your installed version.

    Does CrewAI automatically search for current information?

    Not always. The public basic report and blog example has no search tools connected. For current external information, separately configure search and collection tools, authentication, and result verification.

    Does adding more agents improve accuracy?

    Agent count alone cannot guarantee accuracy. Unclear differences between roles may only increase handoff costs and complexity. First clarify why the work needs dividing, which tools are required, and which deliverables must be verified.

    References

    The images are screenshots quoted from the source course to explain concepts and project structure. The video’s explanations are distinguished from configurations in the public code, current official guidance, and practical application suggestions.

    Original Korean article

  • AI Agent Framework Comparison: Five Options and How to Choose Today

    AI Agent Framework Comparison: Five Options and How to Choose Today

    Search for ways to build AI agents, and CrewAI, AutoGen, OpenAI Agents SDK, Google ADK, and LangGraph appear together. Familiar names do not make the choice easy. Tools for rapid prototyping are compared against tools for finely controlling recovery from failed tasks and waiting for human approval.

    Nomad Coders’ video ‘The Best AI Agent Framework in 2025?’ explains strengths and weaknesses through the creator’s experience implementing the same stock analysis agent with several frameworks. This comparison guide distinguishes the 2025 video’s assessments from current official materials. In particular, changes in maintenance status and features are addressed using official materials checked on October 27, 2026.

    First, distinguish personal experience from a performance ranking

    The creator says the comparison used the same logic, prompts, and tools across frameworks. However, the video does not establish a controlled benchmark for model versions, repeated runs, costs, success rates, or evaluation criteria. Read statements such as ‘you can build it in 20 minutes’ or ‘the best’ as personal experience and preference.

    References to the stock analysis agent’s investment returns do not prove a framework’s superiority either. Investment outcomes depend on other factors, including market conditions and strategy. This guide therefore does not use them as selection evidence.

    For practical work, start with these questions.

    • Task structure: Is the sequence fixed, or must it branch, loop, and resume depending on circumstances?
    • Models and tools: Which models, search, file, and voice capabilities must you connect?
    • Execution state: Do you need to save intermediate results, recover after interruptions, or obtain human approval?
    • Operating environment: Does it fit your team’s programming languages, cloud, security, and deployment requirements?
    • Maintenance: Is its support status clear enough for a new project?

    These answers make it easier to select candidates for your project, rather than search for ‘the best framework.’

    CrewAI: dividing work by roles and tasks

    The video rates CrewAI as a good starting point for learning agents. It finds the structure intuitive: connect Tasks and tools to role-based agents, then combine them in a Crew. Consider it for prototyping work with clear roles and deliverables, such as research followed by writing.

    Source video explaining how CrewAI combines roles and tasks
    Source: Nomad Coders, source video at 02:15. Frame quoted to illustrate the discussion.

    However, ‘good for quick assembly’ is not the same as ‘only useful for demos.’ The current official repository covers both Crews and Flows. Alongside role-based collaboration, it explains event-driven control, state, branching, and integration with ordinary Python logic.

    Treat the video’s claim that going beyond the framework’s structure is difficult as the creator’s usability assessment at that time. That one statement cannot define CrewAI’s current extensibility. Conversely, official guidance on production configurations does not mean your own Crew is ready for safe operation.

    Start with a small task involving about two roles. Try explaining its inputs, outputs, and possible failure points. For concrete setup details, see the CrewAI beginner’s guide.

    AutoGen: check current maintenance guidance before relying on a 2025 recommendation

    The video introduces AutoGen’s conversational collaboration and its Studio, AgentChat, and Core components. It considers AutoGen a suitable option for .NET environments. This helps explain its characteristics at the time. For a new project today, however, the first thing to check has changed.

    AutoGen’s current official README states that the project is no longer maintained and directs new users to Microsoft Agent Framework. It also warns that bug fixes, security fixes, and support are not provided. A migration guide for existing users is linked as well.

    The evidence here is the maintenance notice in the official README. Do not confuse it with whether the GitHub repository is technically archived as read-only. The important question is what fixes and support you can expect for code a new service will depend on.

    The video’s advice that ‘AutoGen is the only choice for C# developers’ should therefore not become a current recommendation unchanged. Microsoft Agent Framework supports .NET and Python. It describes sequential, concurrent, handoff, and group collaboration workflows. For a new Microsoft-ecosystem project, review this successor framework alongside the migration documentation.

    Do not assume an existing AutoGen system can migrate immediately through a simple name change. Review its messaging, tools, state management, and deployment configuration. Then test compatibility and results on a small representative task.

    OpenAI Agents SDK: connecting delegation, tools, and tracing with a compact approach

    The video highlights integration with OpenAI models and tools, tracing, and the experience of developing voice agents. The current official repository also lists Agents, tools, guardrails, sessions, tracing, and human-in-the-loop capabilities.

    In particular, distinguish calling other agents as tools from transferring control through handoffs. Both are forms of delegation, but their designs differ. Does the caller receive a result and keep coordinating, or does another agent take over the conversation?

    Source video explaining connections between a main agent and supporting roles
    Source: Nomad Coders, source video at 05:30. Frame quoted to illustrate the discussion.

    The current official README describes the SDK as provider-agnostic and covers integration with models beyond OpenAI. The video’s statement that support for other models is in beta cannot define the current status of the entire SDK. However, multiple-provider support does not mean every model can use a provider’s hosted tools, voice capabilities, and execution features identically.

    Another point requiring care is the claim that it ‘has the features needed for deployment.’ Tracing and guardrails are useful components. They do not by themselves complete user login, authorization, secret protection, or data retention policies. Separately design who can execute which tools in your application.

    Google ADK: considering development, evaluation, and Google integration together

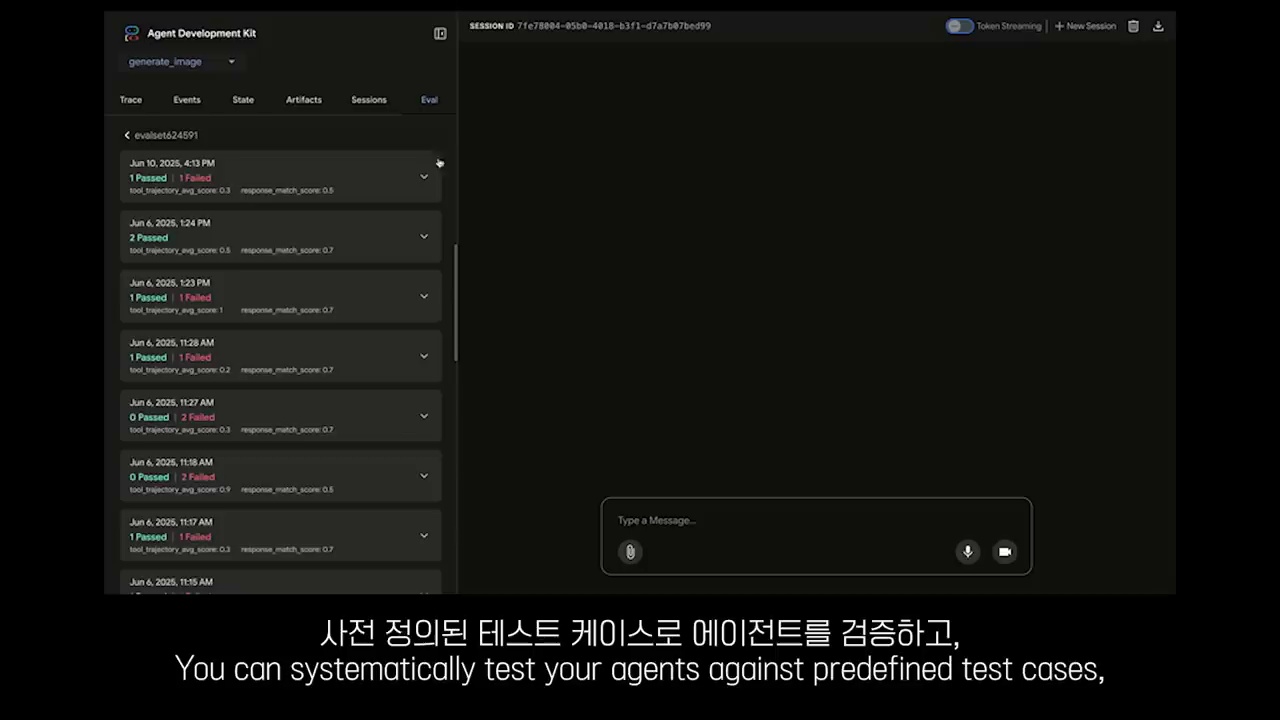
    The video praises Google ADK’s development UI, evaluation features, and Google ecosystem connections. The current Python repository also covers a development Web UI, evaluation runs, and deployment. It describes ADK as optimized for Gemini while remaining model-agnostic.

    Source video introducing Google ADK's testing environment
    Source: Nomad Coders, source video at 08:30. Frame quoted to illustrate the discussion.

    These capabilities matter to teams that want to inspect tool use and execution paths, not just model responses. However, the video’s claims of ‘the only framework with a UI’ and ‘the only framework with evaluation’ are difficult to adopt unchanged. UI and evaluation offerings vary by ecosystem and version. Check whether they fit your development process instead of making exclusive ranking claims.

    Avoid limiting the architecture to a fixed description from 2025 as well. The current ADK repository introduces graph-based Workflows, branching, loops, and state management. Saying it ‘only supports a main agent and subagents’ misses the current guidance.

    A development UI or the ability to run a REST API does not mean production deployment is complete. Check authentication, access controls, cost, quotas, observability, and incident response separately in the actual deployment environment.

    LangGraph: explicitly designing state and control flow

    LangGraph is the creator’s stated favorite. The video describes it as directly building nodes and edges in a graph, rather than assembling roles. This is a personal preference, but it helps explain the design distinction being considered.

    The current official repository describes LangGraph as a low-level orchestration framework for long-running, stateful agents. Its highlighted capabilities include durable execution and recovery, human-in-the-loop interaction, memory, and state management.

    Source video explaining LangGraph's features and control mechanisms
    Source: Nomad Coders, source video at 11:50. Frame quoted to illustrate the discussion.

    This control approach matters when insufficient evidence must trigger more research or risky actions must wait for approval. It also matters when interrupted work must resume from its saved state. However, checkpoints cannot automatically undo every action in an external system. Separately consider how to prevent duplicate side effects, such as sending emails or making payments.

    A ‘small API’ does not mean developing a real service is always easy. Developers may need to take more explicit responsibility for state structures, branching conditions, and error handling. Graph-based control benefits tasks that need it, but may overcomplicate a short, single task.

    Which options should you consider first in different situations?

    These starting points are reconstructed from current official guidance. They do not reproduce a fixed ranking from the video.

    1. You want to quickly test a role-based research and writing pipeline: Consider a small Crew in CrewAI. First check whether roles and deliverables are clearly distinct.
    2. You want an SDK-centered setup connecting tools, handoffs, sessions, and tracing: Consider OpenAI Agents SDK. Check compatibility for each model and feature you plan to use.
    3. Google ecosystem integration and development and evaluation tools matter: Consider Google ADK. Also check the services you need and their deployment requirements.
    4. Control over state, branching, recovery, and approval flows matters: Consider LangGraph. First define the boundary between ordinary code and agent judgment.
    5. You are starting in a Microsoft or .NET environment, or migrating from AutoGen: Review Microsoft Agent Framework alongside the official migration guidance.

    These options are not mutually exclusive. Similar patterns can be implemented in several frameworks. The decisive difference is not whether a feature name appears, but how clearly your team can implement, verify, and maintain the behavior it needs.

    Compare the same small task under the same operating conditions

    Repeated tests with the same inputs are more useful than one impressive demo. Rather than moving an entire workflow at once, choose a small task such as research → evidence organization → review. Compare the following points.

    • Under the same requirements, what sources and tool execution records does it retain?
    • How does it stop when information cannot be found or a tool fails?
    • Can it continue after a person makes corrections or gives approval?
    • Can you identify execution cost, latency, and the number of retries?
    • Can you limit external transmission and modification permissions to the necessary scope?

    Even with the same model, frameworks may use different internal prompts or defaults. Treat this comparison as a suitability test for your work. It is not a universal performance ranking with every variable controlled.

    You do not need to master every framework before starting work. Build a small task with one candidate. Consider another when you identify an unmet requirement. What should endure is more than a particular tool’s syntax. It is a design that explains roles, state, tool permissions, and verification criteria.

    Related reading

    FAQ

    Is learning just one AI agent framework enough?

    You do not need to learn all of them deeply at the outset. Choose a representative task and start with one candidate. Learning shared concepts such as roles, tools, state, and verification also helps when moving to another tool.

    Should AutoGen be recommended for new projects now?

    The current official README announces the end of maintenance and directs users to Microsoft Agent Framework. For new adoption, check that guidance and the successor framework first. Existing systems require a separate review of dependencies and migration scope.

    Is CrewAI only for demos, while LangGraph is the only production option?

    That distinction does not hold. CrewAI also covers workflow execution and control through Crews and Flows. Whatever tool you choose, implement and test production requirements including authentication, permissions, source verification, and recovery from failures.

    Does OpenAI Agents SDK work only with OpenAI models?

    The current official README covers integration with multiple model providers. However, model integration differs from access to particular hosted tools. Check support requirements for each capability you need.

    References

    The images are screenshots used to quote and critique explanations in the source video. The creator’s experiences and preferences are distinguished from current official feature and maintenance guidance and this guide’s practical suggestions. No independent performance benchmark was conducted.

    Original Korean article

  • How to Use Pixel Agents to View Claude Code Work in a Pixel Office

    How to Use Pixel Agents to View Claude Code Work in a Pixel Office

    Running several tasks simultaneously in Claude Code also means switching between terminals more often to check their status. It is hard to see at a glance which tasks are active, which need input, and whether subagents remain. Pixel Agents represents these states as characters in a small pixel office.

    Nate Herk’s video demonstrates visually monitoring activity across multiple terminals and subagents. However, the video dates from February 2026. This guide distinguishes the video’s user experience from official repository guidance checked on October 27, 2026, covering current support, installation steps, status-display limits, and security precautions.

    Pixel Agents Shows the Status of Work

    Pixel Agents represents AI coding agents running in terminals as pixel characters. The official README describes characters moving or displaying indicators as agents write or read files, run commands, or await input or approval.

    In the video, a main agent delegates research roles while an agent in another terminal handles separate work. The user checks which tasks are active in the office view, then returns to the relevant terminal.

    Video showing multiple Claude Code agents represented in a pixel office
    Source: Nate Herk | AI Automation, source video at 00:18. Frame reproduced to explain the discussion.

    A moving character does not mean the result is correct. An activity indicator stopping also does not establish that a requested file is finished or that tests passed. The status screen is an entry point for finding what to inspect; actual output and logs determine completion.

    The small office can highlight workload and intervention points. It is not a workflow diagram mapping data flows or every design decision. Later in the video, the creator also expresses interest in seeing more clearly what agents are building and deciding.

    Differences Between the Video and Current Official Guidance

    Installation requirements and features can change after a video introduces an early tool. Check these differences before treating this video’s instructions as current guidance.

    • Operating systems: The video describes testing focused on Windows at the time. The current official README lists Windows, Linux, and macOS together in its requirements.
    • Execution options: The documentation describes both a VS Code extension and a standalone CLI for viewing the office in a browser.
    • Team display: The video says Agent Teams visualization is not yet available. The current README lists displays for subagents and persistent teammates as features.
    • Activity detection: The video describes reading activity logs. Current documentation distinguishes the primary hook-event mechanism from a fallback that infers status from session transcripts.

    This guidance reflects the official repository examined. Check the installed Marketplace version’s description and actual behavior to see whether every feature works identically in your Claude Code environment.

    The repository’s goal of supporting multiple agents and editors does not mean every roadmap product is already available. The README presents Claude Code as the current reference implementation and distinguishes other integrations from the roadmap.

    How to Get Started in VS Code

    The current official README provides separate getting-started instructions for the VS Code extension and standalone CLI. In VS Code, first check your configured Claude Code CLI and the extension’s version requirements. The documentation examined requires VS Code 1.105.0 or later.

    The basic process is as follows.

    1. In Marketplace, find publisher pablodelucca‘s Pixel Agents, verify it, and install it.
    2. Open your working folder and the Pixel Agents panel beside the terminal.
    3. In the current guide’s + Agent, choose a working directory and launch Claude Code.
    4. Request a small private task. Check whether activity and waiting indicators match the actual terminal state.
    5. When needed, compare detailed status in Debug View with the original terminal.

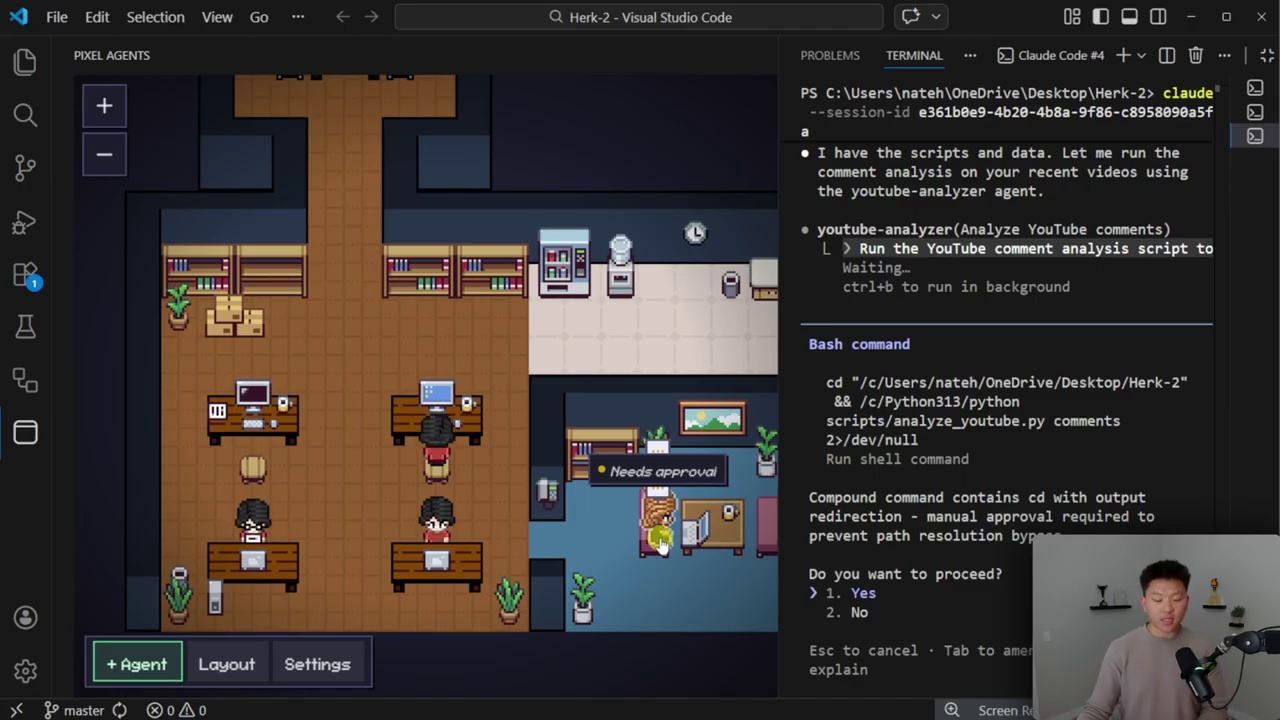
    The video’s early interface shows that clicking + Agent opens a terminal immediately. The current README describes a directory-selection step. A screen differing from the video does not necessarily mean installation failed.

    Video frame showing an agent waiting for the user's permission approval
    Source: Nate Herk | AI Automation, source video at 01:00. Frame reproduced to explain the discussion.

    The presenter’s reported detection problem with spaces and periods in folder names should also be treated as experience from that environment. Do not assume it is a universal constraint across current versions or rename existing projects unconditionally. Check current documentation, detection scope, and connection status first.

    This guide compares the video with documentation. The extension was not separately installed to reproduce the results, and the user’s development environment was not changed.

    Office Layout and Debug View Serve Different Purposes

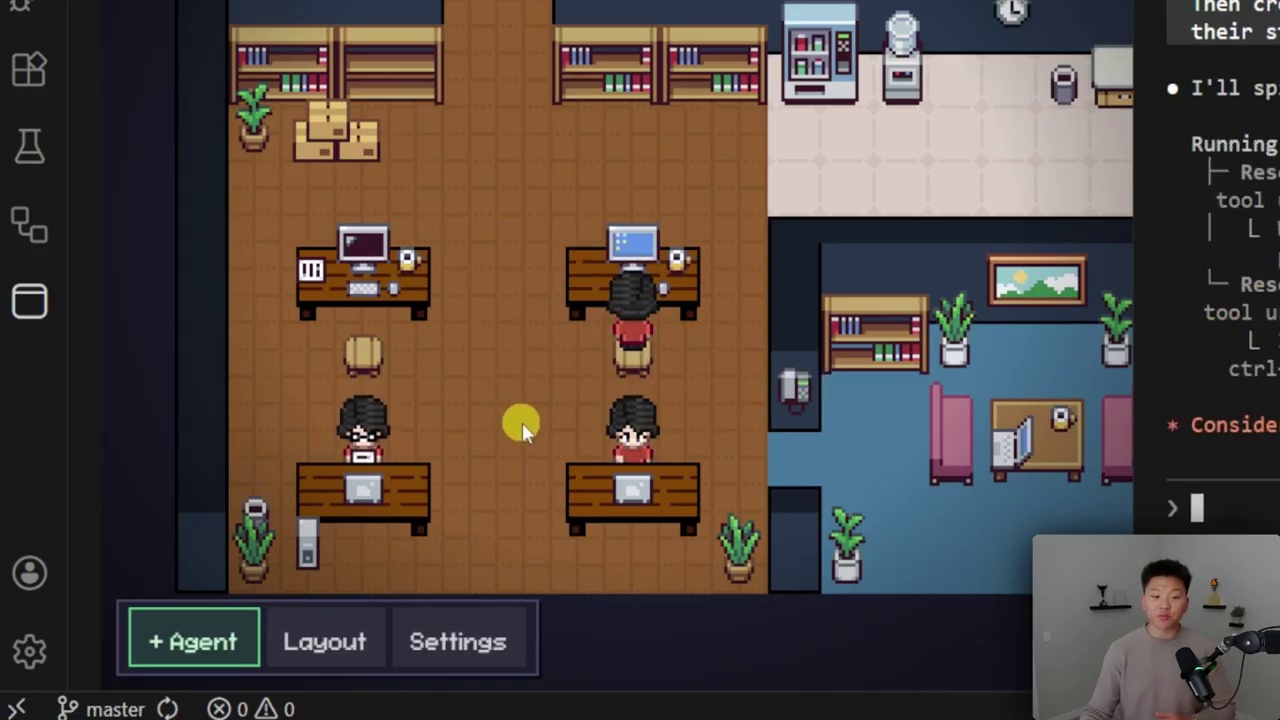
    Pixel Agents has an editor for placing floors, walls, furniture, and other elements. This can add visual enjoyment and make the space for monitoring several tasks feel familiar. The current README also describes directory-linked zones, saved layouts, and external assets.

    Video frame showing furniture and layout editing in the pixel office
    Source: Nate Herk | AI Automation, source video at 06:38. Frame reproduced to explain the discussion.

    Moving a desk does not change the model or separate an agent’s file permissions. Distinguish visual layout from actual execution settings. Responsibility for dividing work lies in agent instructions and the execution structure.

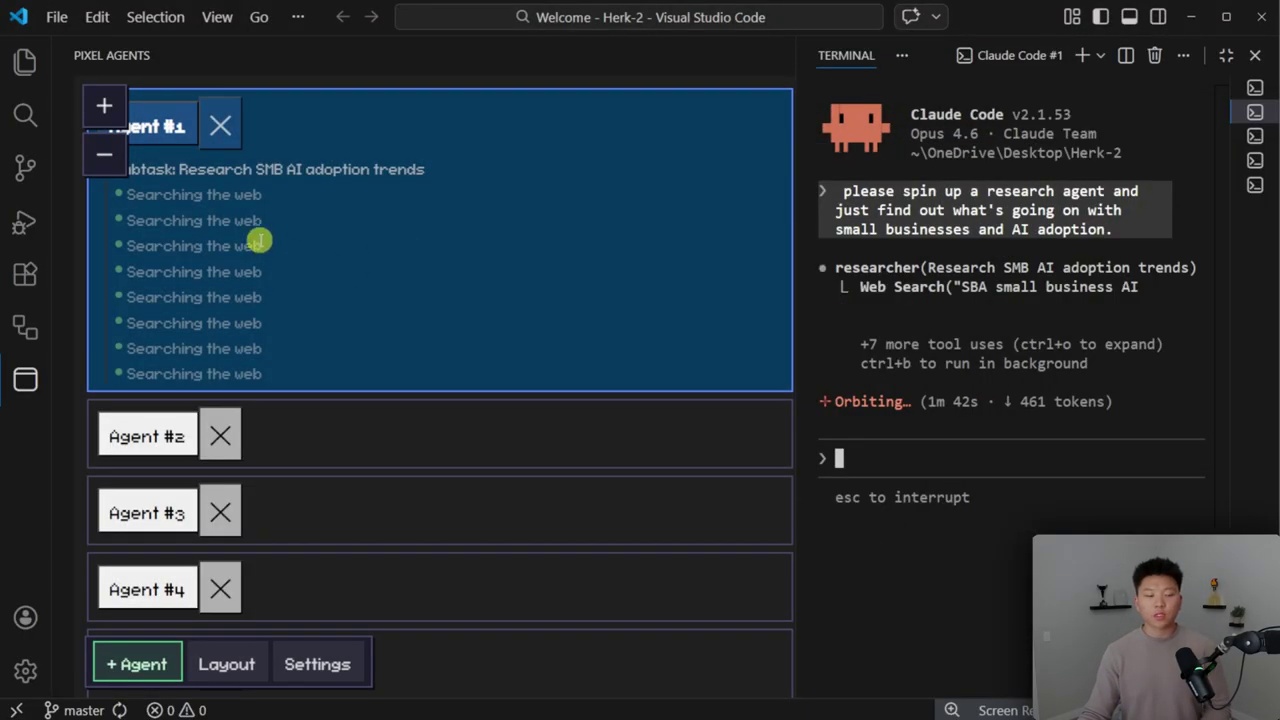
    Debug View, by contrast, is a place to inspect connection status and agent data. If an agent is missing onscreen, do not automatically resend the request. First check whether its session falls within detection scope and compare the latest displayed information.

    Video frame showing Debug View for inspecting detailed agent activity
    Source: Nate Herk | AI Automation, source video at 07:10. Frame reproduced to explain the discussion.

    This visualization may be particularly useful with multiple terminals, easily missed approval requests, or long-running tasks alongside other work. However, compare it in your own work to determine whether it reduces checking time. The video alone cannot establish a numerical productivity improvement.

    Distinguish Parallel Terminals, Subagents, and Agent Teams

    Several characters sharing an office does not mean they all collaborate in the same way.

    • Work across multiple terminals: Separate sessions handle separate requests. Displaying them together does not automatically share materials or context.
    • Subagents: A parent agent delegates specific tasks. Check the scope of requests and how results are collected.
    • Agent Teams: Current Pixel Agents documentation describes displaying teammates, roles, and lifecycles. Check the underlying tool’s features and settings for actual team coordination and permissions.

    Do not directly equate character counts with employee numbers or independent verification counts. Several agents may receive the same incorrect materials and produce similar answers. More importantly, use the monitoring screen to locate and inspect each task’s terminal and deliverables.

    Do Not Judge Security by a Cute Interface or Publisher Verification

    The video creator says they checked network calls and suspicious behavior before installation and felt reassured. This reflects their review experience at the time. It is not an independent security audit covering every version and installation environment. Repository stars and publisher verification do not guarantee code or dependency safety either.

    Given current features, describing the tool as merely reading logs without touching commands or settings is insufficient for judging security. The official README describes hook configuration, authenticated event delivery to a running server, and launching agents in terminals. Check which settings installation and use change, and what the tool can access.

    The following items deserve particular attention.

    1. Source and version: Check the official repository, publisher, installed version, and changelog.
    2. Permission approval: Skip Permissions and similar permission-check bypass options should not be enabled for convenience. Also check the warning that an enabled setting may persist.
    3. Detection scope: Consider whether you need a setting that also displays sessions from other workspaces.
    4. Record exposure: Check logs, prompts, filenames, and screenshots for customer materials or secrets.
    5. Basic verification: Even when an approval request appears onscreen, inspect the actual command and target files before deciding.

    Visualization can alert you to pending approval. It does not judge the safety of the requested command for you. Avoid mechanically clicking approval buttons while watching several agents.

    With the Standalone CLI, the Access URL Can Also Be Sensitive

    The current official README also explains how to run the standalone CLI on Node.js 20 or later and view the office in a browser. This is an option to consider for terminals outside VS Code or remote work.

    The important difference is the addition of a web server. The documentation says the default address uses local loopback. It warns that binding to all interfaces can expose the UI and WebSocket to the local network. Changing the address to enable outside access is not merely a convenience setting.

    The token-bearing URL printed by the server can also grant access to hook configuration and terminal operations. Do not paste it into public chats, screenshots, or documents. An address looking local does not make it safe or suitable for public sharing.

    Consider reducing functionality when you only need observation, for example through the documented option to disable terminals. However, enabling that option does not resolve every access-control or data-exposure issue.

    The Best Use Is to Observe, Verify, and Intervene When Needed

    Pixel Agents presents coding-agent activity through a familiar visual interface. Instead of constantly switching terminals, scan the status view. Use it as an entry point for returning to tasks needing approval or closer inspection.

    Assess its usefulness on a small task with the following questions.

    • Do onscreen active and waiting states match the actual terminal?
    • Can you notice approval requests sooner?
    • Can you easily inspect deliverables and test results for work that appears complete?
    • Does the visual appeal help you check status, or does it distract from work?

    Busy pixel characters matter less than what ran, what results remain, and whether human judgment is needed now. Visualization is a tool for finding where to verify, not a replacement for verification. That is the more appropriate way to view it.

    Related Reading

    FAQ

    Is Pixel Agents Only Available on Windows?

    The video describes early testing focused on Windows, but the current official README lists Windows, Linux, and macOS. Separately check the requirements for your intended extension version and runtime environment.

    Does a Character Stopping Mean the Task Is Complete?

    Status indicators alone cannot establish completion or quality. Check the original terminal’s response, generated files, execution and test results, and unverified items.

    Does It Currently Display Agent Teams?

    The official README examined lists displays for subagents and Agent Teams teammates, roles, and lifecycles. Distinguish this from the video’s earlier statement that the feature was unsupported. Check the support provided by your installed version.

    Can I Skip Security Review for an Extension from the Official Publisher?

    No. Publisher identity and code safety are separate matters. Review versions, dependencies, configuration changes, file and log access, server exposure, and permission-bypass options for your environment.

    References

    The images are captures used to explain and critique the source video’s user experience. The video’s descriptions, current repository feature guidance, and this guide’s application suggestions are distinguished. They do not indicate that independent execution reproduction or a security audit was completed.

    Original Korean article

  • South Korea Festivals in November 2026: Fireworks, Chrysanthemums, and Food

    November offers many travel options, from parks with lingering chrysanthemums to seaside fireworks and markets serving seasonal food. But ‘November festivals’ require very different plans if they end on the first day or begin on the final weekend.

    South Korea’s November 2026 festival schedule is organized here by date and region. These 14 major festivals have this year’s dates confirmed through Korea Tourism Organization, local government, and official tourism agency guidance. This is not an exhaustive nationwide list. It also includes festivals that begin in October and continue into November.

    November 2026 festivals at a glance

    All dates below are for 2026. Click a festival’s name to open its official information page. Not every performance or activity runs every day throughout the festival, so check the dates of your preferred programs too.

    Festival Full event dates Region Main venue Highlights
    Nowon Moonlight Walk 10.16~11.08 Nowon, Seoul Danghyeoncheon Stream area Light sculptures and nighttime public art
    Iksan Ten Million Chrysanthemums Festival 10.23~11.01 Iksan, Jeonbuk Central Sports Park area Chrysanthemum sculptures and nighttime scenery
    Korea Chrysanthemum Festival 10.23~11.08 Hampyeong Hampyeong Expo Park Large chrysanthemum displays, bonsai, and activities
    Buyeo Chrysanthemum Festival 10.30~11.08 Buyeo, Chungnam Gungnamji Pond area Chrysanthemum displays inspired by Baekje culture
    Masan Gagopa Chrysanthemum Festival 10.31~11.08 Changwon, Gyeongnam March 15 Marine Nuri Park, Happo Waterfront Park, and Marine New City areas Sea views, chrysanthemums, and cultural performances
    Cheongsong Apple Festival 11.04~11.08 Cheongsong, Gyeongbuk Yongjeoncheon Stream area in Wolmak-ri, Cheongsong-eup Apple activities and sales of local agricultural specialties
    Goesan Kimjang Festival 11.05~11.08 Goesan, Chungbuk Organic Expo Plaza and Sports Complex areas Kimchi-making activities and kimchi market
    Jeju Olle Walking Festival 11.05~11.07 Jeju Jeju Olle Routes 19 and 20 Walking, village culture, and performances
    Gumi Ramyeon Festival 11.06~11.08 Gumi, Gyeongbuk Old downtown, including Gumi Station and Yeokjeon-ro Various ramyeon dishes and activities
    Gimhae Buncheong Ceramics Festival 11.06~11.10 Gimhae, Gyeongnam Lotte Garden Park Buncheong pottery exhibitions, sales, and hands-on making activities
    Busan Fireworks Festival 11.07 Busan Gwangalli Beach and Gwangandaegyo Bridge area Multimedia fireworks show over the sea
    Goheung Yuja Festival 11.12~11.15 Goheung Yuja festival grounds in Handong-ri, Pungyang-myeon Yuja activities, citrus groves, and illuminated gardens
    Pohang International Fireworks Festival 11.19~11.21 Pohang, Gyeongbuk Yeongildae Beach International fireworks shows and nighttime cultural events
    Paju Jangdan Soybean Festival 11.27~11.29 Paju, Gyeonggi Imjingak Plaza Jangdan soybeans, local agricultural specialties, and food

    The Iksan chrysanthemum festival’s final day is November 1. For more flexibility when choosing a chrysanthemum festival, compare Buyeo, Hampyeong, and Masan, which continue through November 8.

    Choosing a festival around your weekend plans

    • November 1: A good day to explore autumn festivals continuing from October, including the final day of Iksan’s chrysanthemum festival.
    • November 7–8: Options include the Busan Fireworks Festival, Cheongsong Apple Festival, Gumi Ramyeon Festival, and Goesan Kimjang Festival. Note that Busan’s fireworks festival runs only on November 7.
    • November 14–15: You can plan a trip to Korea’s southern region around the Goheung Yuja Festival.
    • November 21–22: The Pohang International Fireworks Festival ends on November 21. Do not book under the assumption that it continues on Sunday, November 22.
    • November 28–29: The month’s final weekend brings the Paju Jangdan Soybean Festival. Consider it for a trip to enjoy local food and markets in the Seoul metropolitan region.

    For a walking trip, also look at the Jeju Olle Walking Festival on November 5–7. It continues through Saturday, making it suitable for a trip that includes Friday.

    For fireworks and nighttime scenery: Busan, Pohang, and Nowon

    Busan Fireworks Festival: November 7, a night at Gwangalli

    The Busan Fireworks Festival combines music, lighting, and fireworks against Gwangalli Beach and Gwangandaegyo Bridge. Official information lists an invited international fireworks show and the Busan Multi-Fireworks Show as major programs.

    If you plan to use paid viewing seats, first check seat categories and booking availability. Korea Tourism Organization lists regular tickets at KRW 100,000 for R seats and KRW 70,000 for S seats. These are paid-seat prices, not confirmation of remaining seats or on-site ticket availability.

    Before visiting, check the official Busan Fireworks Festival website for the day’s schedule, traffic restrictions, and viewing guidance. Avoid planning on the assumption that arriving at a particular spot guarantees a good view.

    Pohang International Fireworks Festival: November 19–21, fire and light at Yeongildae

    The Pohang International Fireworks Festival takes place at Yeongildae Beach. Korea Tourism Organization lists international fireworks shows, media facades, a night carnival, and performances among its main attractions.

    Check the full festival dates separately from the main fireworks show timetable. A three-day festival does not mean fireworks shows of the same scale run throughout all three days. Check your preferred day’s program before booking accommodation and transport.

    Nowon Moonlight Walk: a light exhibition along Danghyeoncheon through November 8

    Consider Nowon Moonlight Walk if you prefer an evening stroll in Seoul to a long-distance trip. This nighttime festival centers on lanterns, light sculptures, and public art along Danghyeoncheon Stream.

    Admission is listed as free. However, exhibition viewing hours may differ from weekend performance and guided-program schedules. Check separately if you want a particular program.

    Early November matters for chrysanthemum festivals

    Iksan Ten Million Chrysanthemums Festival: through November 1

    Iksan features chrysanthemum gardens, large sculptures, chrysanthemum bonsai exhibitions, and nighttime scenery. This year’s information lists free admission. Remember, however, that November 1, the final day, is the only November date available for a visit.

    Buyeo Chrysanthemum Festival: Baekje and chrysanthemums at Gungnamji Pond

    The Buyeo Chrysanthemum Festival takes place around Gungnamji Pond. Its distinctive displays depict Baekje history and culture, including the gilt-bronze incense burner and Sabi Gate. Admission is listed as free, but that does not mean every activity or food purchase is free.

    Korea Chrysanthemum Festival: large displays and activities in Hampyeong

    Hampyeong’s Korea Chrysanthemum Festival brings together themed chrysanthemum displays, bonsai, performances, and activities. Unlike some other chrysanthemum festivals, it charges admission, so budget accordingly.

    Korea Tourism Organization lists individual adult admission purchased on-site at KRW 7,000. Advance-booking discounts are listed as ending on October 22. November visitors should not mistake that expired discount for a price currently available. Check official guidance for age-based, group, and free-admission conditions.

    Masan Gagopa Chrysanthemum Festival: combine sea views and chrysanthemums

    The Masan Gagopa Chrysanthemum Festival takes place across March 15 Marine Nuri Park, Happo Waterfront Park, and Marine New City. It features chrysanthemum exhibitions and cultural performances, with admission listed as free.

    Venues are spread across several spaces, so first check the locations of the exhibitions and performances you want to see. Do not assume fireworks or traditional falling-spark displays operate continuously throughout the festival.

    For seasonal food and hands-on activities

    Cheongsong Apple Festival and Gumi Ramyeon Festival

    The Cheongsong Apple Festival runs November 4–8. Alongside sales of apples and local agricultural specialties, it features apple-themed activities and participatory programs. Admission is free, while some activities cost extra.

    The Gumi Ramyeon Festival runs November 6–8 in the old downtown, including Gumi Station and Yeokjeon-ro. Attractions include varied ramyeon dishes, freshly fried ramyeon noodles, and making activities. Festival admission is listed as free, but food purchases cost extra.

    In particular, Korea Tourism Organization’s Gumi Ramyeon Festival page labels some food information as material from the previous year, 2025. Do not treat old menu prices as this year’s selling prices. Choose based on official 2026 information and on-site menus.

    Goesan Kimjang Festival: prepare differently for sightseeing and kimchi making

    The Goesan Kimjang Festival runs November 5–8 around Organic Expo Plaza and the Sports Complex. Distinguish advance-reservation activities, such as one-stop and drive-through kimchi making, from the kimchi market and on-site participation programs.

    The official website also introduces a walk-in kimchi-making program that needs no reservation. This does not mean every kimchi-making program is available without booking. First check registration, quantities, and participation fees for your preferred option. The county office also notes that drive-through kimchi making has moved to the Sports Complex this year.

    Goheung Yuja Festival: November 12–15, a trip among yuja groves

    The Goheung Yuja Festival takes place around Handong-ri, Pungyang-myeon. Highlights include yuja activities such as making yuja preserves, a direct-sales market, grove walking paths, and illuminated nighttime gardens.

    General admission is listed as free, but some activities and programs charge fees. Check on-site arrangements separately for activities such as yuja harvesting, which may have participant limits and set operating hours.

    Paju Jangdan Soybean Festival: a market on November’s final weekend

    This year’s dates confirmed through Paju City’s official information are November 27–29, at Imjingak Plaza. Be careful not to reuse another year’s dates or a schedule from an unofficial post.

    Plan a trip to explore Jangdan soybeans, local agricultural specialties, and food. The official page also includes past years’ price tables, so check this year’s information when estimating purchase costs.

    Walking and making activities: Jeju Olle and Gimhae buncheong ceramics

    Jeju Olle Walking Festival: November 5–7, Routes 19 and 20

    Jeju Tourism Organization’s Visit Jeju describes this year’s festival as a walking event on Jeju Olle Routes 19 and 20. Walkers encounter performances, exhibitions, activities, and village food along the way.

    The listed standard participation fee is KRW 30,000, with discount conditions provided separately. However, Visit Jeju lists the advance registration deadline as October 9. To participate now, ask the organizer about additional registration or which activities remain accessible. Do not book flights first and assume you can join every program on arrival.

    Gimhae Buncheong Ceramics Festival: November 6–10, Lotte Garden Park

    The Gimhae Buncheong Ceramics Festival features buncheong pottery exhibitions and sales, plus pottery-wheel activities and mug decorating. This year’s Korea Tourism Organization listing gives the venue as Lotte Garden Park in Gimhae. Do not enter a venue from an older festival review as your destination without checking.

    Activities may have different procedures and fees, so check registration for your chosen program. Do not treat pottery sales discounts on the information page as the same thing as festival admission or activity fees.

    Recheck these four things before leaving

    1. This year’s dates and detailed timetable: Check festival dates, main performances, and activity registration times separately.
    2. Admission and additional costs: Even with free admission, food, materials, paid seats, and parking may cost extra.
    3. Weather and event-change notices: Fireworks and outdoor exhibitions may operate differently depending on the weather. Check notices issued on your departure day too.
    4. Transport and the trip home: Check official traffic restrictions, shuttle and parking guidance, and your last available transport connection. Do not simply follow routes from older reviews.

    A long period on a festival calendar does not mean the main event repeats throughout that period. For example, Korea Tourism Organization’s Unjeong Lake Park listing combines fireworks-show dates with the operating period of a subsequent illuminated garden. Do not interpret that as daily fireworks in November.

    Related travel reading

    References and verification basis

    Festival names in the table link to their official information pages. Korea Tourism Organization’s festival descriptions are based on materials submitted by operating organizations. This year’s guidance from local governments and official tourism agencies was also checked.

    Dates, venues, and fees were checked as of October 28, 2026. They may change due to organizer circumstances or weather. Recheck official notices before booking or paying, and again on your departure day.

    FAQ

    Does this include festivals that did not begin in November?

    Yes. Festivals starting in October were included if they have dates available for visits in November. The table shows full event periods and distinguishes events ending on November 1, such as Iksan’s chrysanthemum festival.

    Are all November festivals free?

    No. The Korea Chrysanthemum Festival charges admission, and the Busan Fireworks Festival offers paid viewing seats. Even free-admission events may charge for food, activities, or materials. Also check application requirements and participation fees for walking and kimchi-making programs.

    When are the Pohang International Fireworks Festival and Paju Jangdan Soybean Festival?

    Officially confirmed 2026 dates are November 19–21 for the Pohang International Fireworks Festival and November 27–29 for the Paju Jangdan Soybean Festival. Recheck each organizer’s guidance for detailed main-performance and activity times.

    Where should I check for changes immediately before visiting?

    Start with the official information linked from festival names in the table, plus festival and local government websites. Use the latest notices before departure to assess weather changes, traffic restrictions, paid-seat availability, and activity registration.

    Original Korean article

  • Vaultaire’s AI App Business: Search Traffic and Revenue Explained

    Vaultaire’s AI App Business: Search Traffic and Revenue Explained

    Apps that hide photos and files already compete in a crowded market. Vaultaire’s AI app business case is interesting because it used specific questions people ask online to attract users, rather than endlessly adding new features.

    We reviewed AI Biz PT’s commentary video alongside the Starter Story founder interview on which it was based. Three elements stand out. A product solving a narrow problem, content answering search questions, and pricing that lets users try before paying. However, the founder’s reported revenue should not be treated as an earnings formula anyone can reproduce.

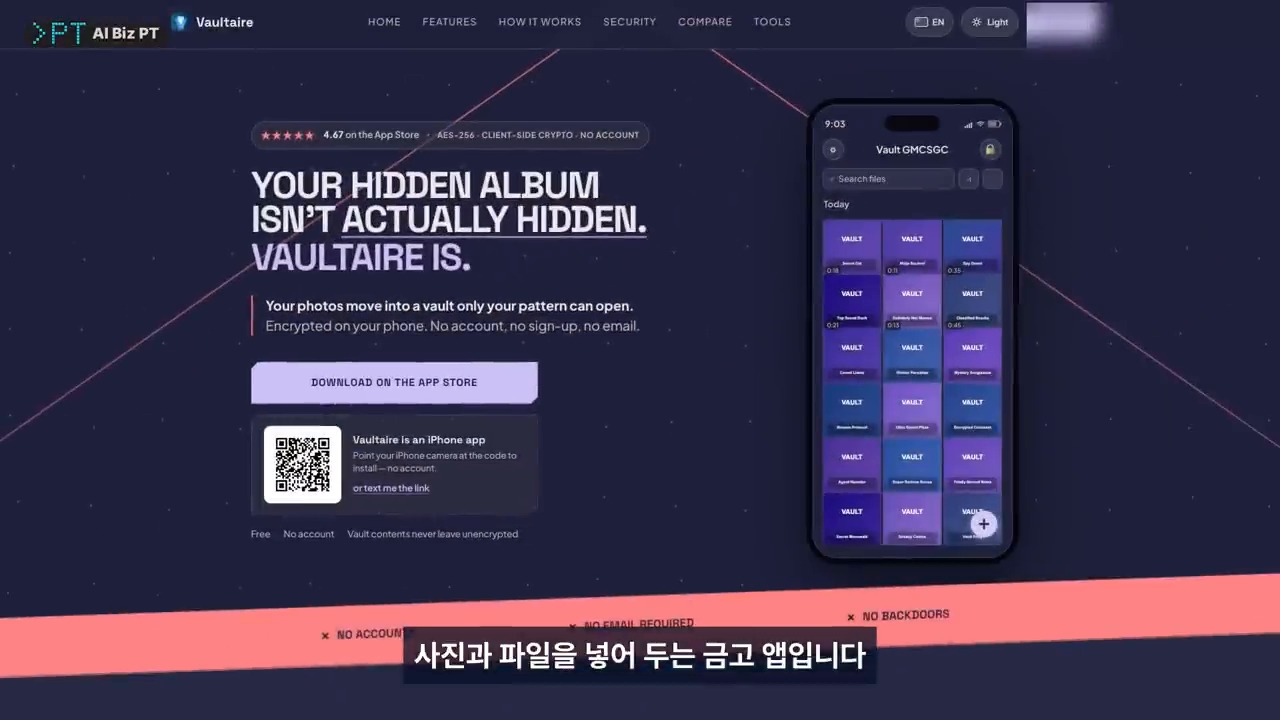
    Introduction to Vaultaire's photo and file vault app
    Source: AI Biz PT video, 00:45; original interview by Starter Story. A video scene showing Vaultaire’s product positioning. Current features were checked separately against official documentation. Scene quoted for commentary and criticism.

    What kind of app is Vaultaire?

    Vaultaire is a vault app that encrypts and stores photos, videos, and files on iPhone and iPad. Its official website describes starting without a separate identity account and unlocking vaults with a pattern. It offers separate free and paid Pro features.

    Founder Rasty Turek says in the interview that coding agents helped him build his first iOS app in about 3 weeks. He also says he did not personally write a single line of code or website copy. Using AI to write code does not mean human judgment was absent from problem selection, review, launch, or operations.

    He describes previous experience in enterprise business and several startups. Presenting this as someone succeeding with a button press and no development or business experience would erase important conditions.

    What does $41,000 a month mean?

    The original interview describes growth from $66 in first-month revenue to $41,000 in one month about six months later. The founder puts daily revenue at the time at $2,000–$3,000, while the on-screen explanation mentions about $2,000.

    The basis for interpreting these figures needs to be clear.

    • Source: The figures come from the founder’s statements and analytics screens presented in the program. They were not independently reconciled against accounting records or bank deposits.
    • Revenue versus net profit: The video describes the amounts as revenue before Apple’s fees. They are not net profit after taxes, refunds, development costs, and operating expenses.
    • Monthly revenue versus MRR: A month’s revenue that includes lifetime purchases cannot be treated as monthly recurring revenue. The founder also says MRR is low because of the share of lifetime purchases.
    • Timing: These results cover a specific period. They do not establish that the app currently earns the same amount or will sustain it.

    The Korean-won amount in the Korean video’s title is also an exchange-rate conversion. Do not interpret it as actual take-home earnings at current rates or guaranteed side-business income.

    Finding web questions instead of competing in App Store search

    The founder judged App Store search competition difficult because established photo vault apps already had longstanding user bases and downloads. He says he focused instead on web search questions related to his product.

    For example, someone searching for ‘how to store photos securely on an iPhone’ may not have chosen an app yet. Such readers need guidance explaining built-in features and differences between alternatives before advertisements listing feature names.

    The point is not that he found a market without competitors. Rather, he chose a different entry point where users seek solutions in an already competitive market.

    To apply this elsewhere, first examine how closely search queries relate to your product. Even substantial traffic offers little reason to buy if your product cannot solve the question. Conversely, a low-volume query can be worth considering if it addresses a real user problem.

    What you improve matters more than publishing once a day

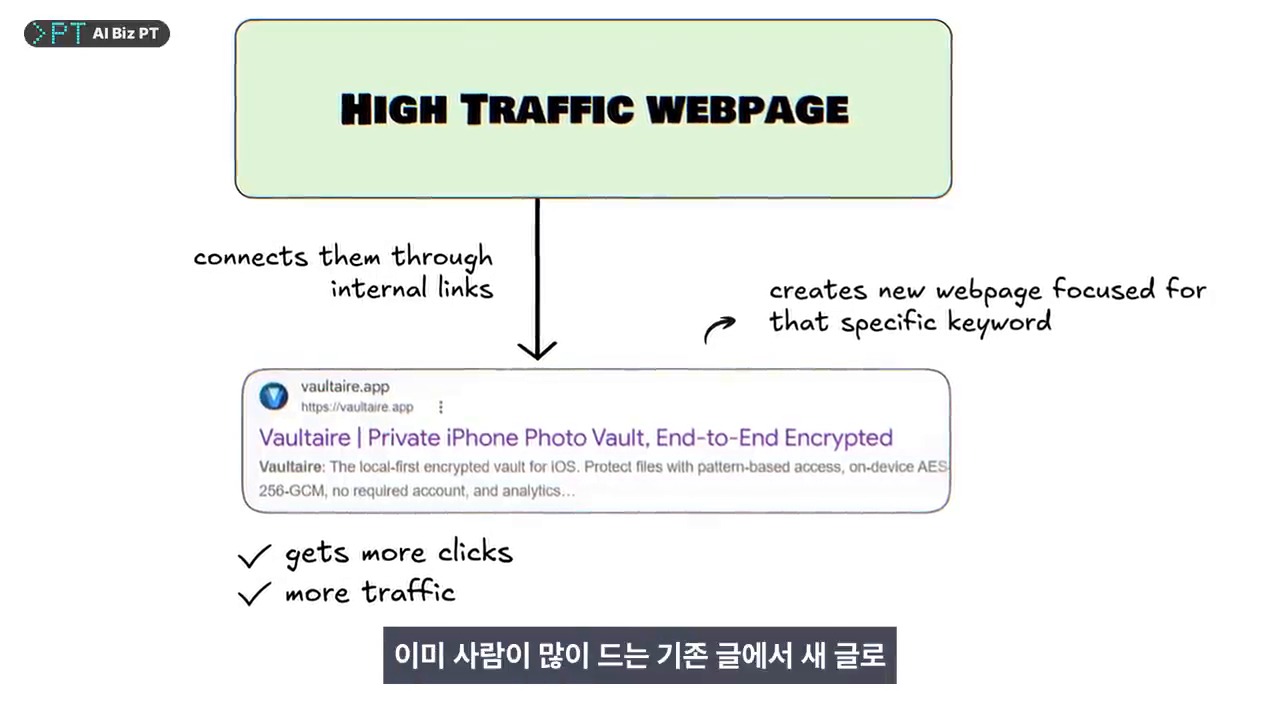
    The interview describes a relatively simple workflow. AI connected to Google tools examines search data and identifies questions getting impressions but not visits. It creates guides for those questions and adds internal links from existing posts to the new ones.

    Explanation of search-question guides and internal links from existing pages
    Source: AI Biz PT video, 04:00; original interview by Starter Story. The video’s explanation of search traffic and internal linking. This diagram does not guarantee ranking improvements. Scene quoted for commentary and criticism.

    High impressions and low clicks alone are not a reason to start with a new article. Causes can include low rankings, titles that miss search intent, or insufficient explanations in existing posts.

    For practical use, the following sequence is safer. It is an application framework based on Google’s official metric definitions, not an exact recreation of the interview’s setup.

    1. Review queries alongside their linked pages in Search Console. Compare impressions, clicks, CTR, and average position over the same period and under the same conditions.
    2. Check whether an existing post can answer the question. Distinguish cases needing a revised title and introduction from those needing a separate article.
    3. Read the search results yourself. Determine whether readers want instructions, comparisons, pricing, or troubleshooting.
    4. Strengthen the answer with information you have directly verified. Include the product’s actual features, limitations, and conditions of use.
    5. Link naturally from related posts. Place internal links and product guidance where visitors have a reason to take the next step.
    6. Keep a revision history and observe under consistent conditions. Measure search clicks, product visits, installations, and purchases as separate stages.

    Search Console shows your own site’s search performance. Keyword Planner is an advertising keyword research tool; its data is not the same. The interview’s explanation of connected tools does not mean your Search Console results and advertising keyword data automatically match.

    Search CTR, the website-to-App Store visit rate, and the post-download payment conversion rate each have different denominators. Combining them into a single ‘conversion rate’ makes it hard to identify which stage improved.

    One post a day is not Google’s ranking formula

    The founder says he published one guide a day and Google took about 3–4 days to recognize new posts. That is an account of this site’s experience, not a guaranteed indexing time for other sites.

    Nor does the interpretation that ‘Google likes one post a day’ constitute an official rule. Rather than focusing on generative AI use itself, Google emphasizes accuracy, quality, relevance, and added value for users. It warns that generating pages at scale without adding value may violate its spam policies.

    The key decision is not simply how much to publish. First ask whether a post merely rewrites existing explanations or provides a better answer to a reader’s question. AI can help draft and organize data, but it cannot fabricate genuine user experience or product verification.

    Pricing assessed beyond first-day payment rates

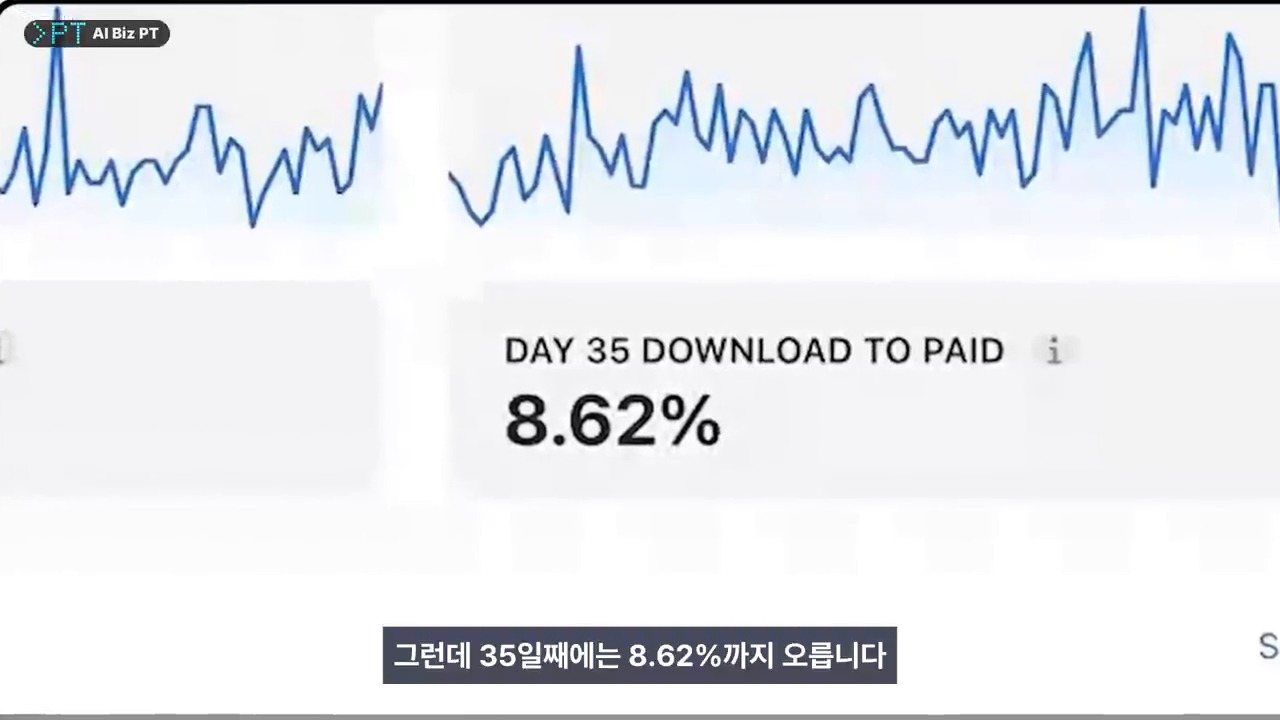
    The video shows payments relative to downloads at 5.47% on DAY 1 and 8.62% on DAY 35. The founder says more people purchase while using the app, even if they do not pay initially.

    Video screen showing an 8.62 percent download-to-payment conversion rate on DAY 35
    Source: AI Biz PT video, 05:27; original interview by Starter Story. The video’s DAY 35 metric. This is not independent performance verification; the denominator and observation conditions were not verified. Scene quoted for commentary and criticism.

    This screen alone cannot prove that increased trust caused more purchases. A longer observation period can raise the cumulative payment rate. It is also necessary to check whether the cohort is identical and how the denominator and metric are defined.

    Still, a practical question remains. Can users assess your product’s value immediately, or only after using it over time for storage, records, or work? That difference can inform the initial payment prompt and the scope of free access.

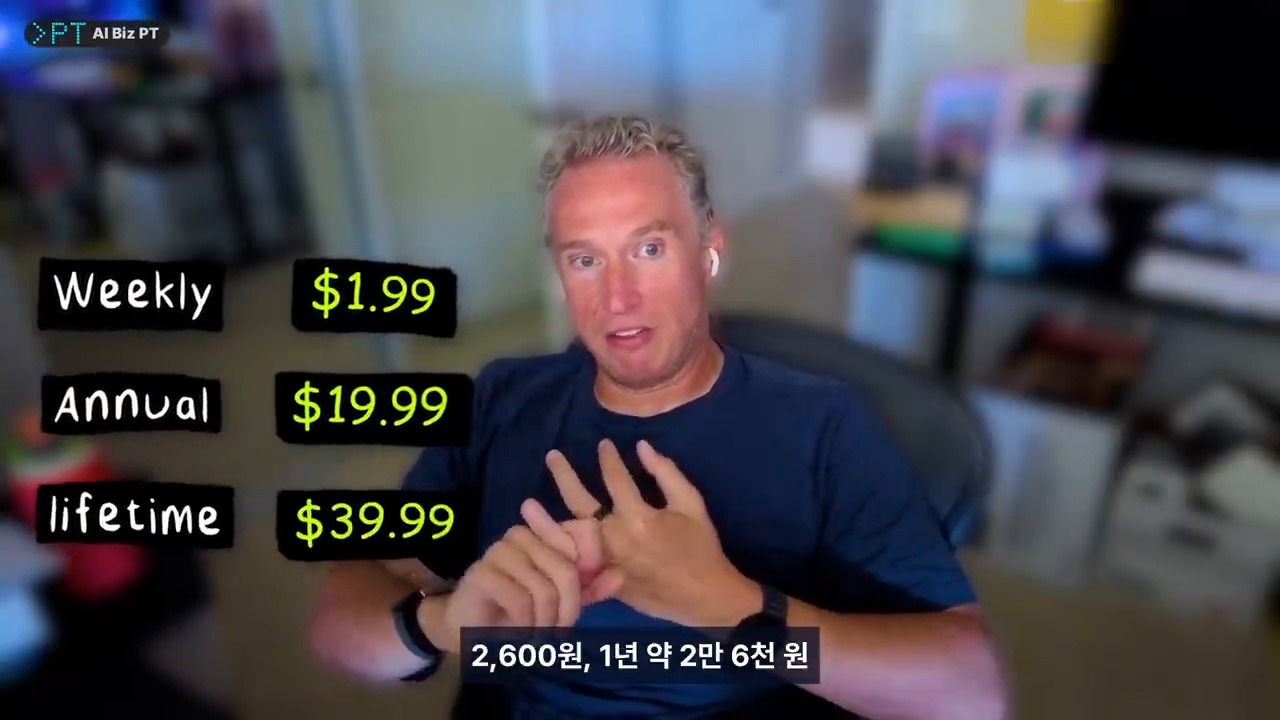
    Prices shown at the time of the video were $1.99 weekly, $19.99 annually, and $39.99 for lifetime access. This is not a verified table of current Korean App Store prices. Check the latest in-app terms before purchasing.

    Comparison of Vaultaire's weekly, annual, and lifetime prices in the video
    Source: AI Biz PT video, 05:37; original interview by Starter Story. Dollar prices presented at the time of recording. Current App Store prices may differ by country. Scene quoted for commentary and criticism.

    The founder estimates that about 60% of purchasers choose lifetime access, contributing more than 80% of revenue. These shares come from his interview explanation, not a comparison against precise settlement records.

    Lifetime access can help bring in cash early. However, future update and customer support obligations remain. Low server costs do not eliminate long-term costs, nor does the same pricing suit every app.

    Separate the video’s security explanations from official documentation

    Product promises must remain accurate even in a business case study. Vaultaire’s official website and privacy policy reveal areas where the video’s brief explanations need qualification.

    • Local encryption does not mean no external services. Official guidance describes iCloud backup that encrypts data on the device before storing it in CloudKit. It says backup is enabled by default and can be turned off.
    • Losing a pattern does not immediately mean recovery is impossible. The official FAQ describes a recovery phrase. It explains that the developer cannot recover data if both the pattern and recovery phrase are lost.
    • No identity account does not mean no analytics data. The policy states that app usage analytics and crash diagnostics are enabled by default and can be disabled in settings. Website analytics are described separately.
    • Encryption does not guarantee safety in every situation. The official security documentation also includes unlocked devices, the operating system, and the app’s implementation within its trust boundary.

    The privacy policy also describes advertising attribution measurement. That does not prove any actual advertising expenditure. However, the interview’s account of ‘growth without advertising’ does not establish a permanent no-advertising operating policy either.

    The story about the FBI requesting help is the founder’s anecdote. It is not a separately verified investigative record or independent security audit, so it was not used as proof of security performance. This article is also not a review based on installing the app and independently testing its encryption or recovery features.

    Connect operations rather than merely automate publishing

    The takeaway from Vaultaire is not that ‘AI makes money on its own.’ It is the connection between user problems, search questions, product introductions, pricing, and measurement in one flow.

    You can start small. Choose one question already generating impressions for your site and check whether your existing explanation is sufficient. If a new article is needed, verify the actual features and limitations before publishing. Place product guidance where readers have a reason to take the next step.

    Start by delegating data organization and suggestions for improvement to AI. Keep public publishing and changes to pricing or security promises subject to review. When following success stories, replicate this sequence of judgment and verification before trying to replicate the numbers.

    Related reading

    References

    Images in this article quote explanatory scenes from AI Biz PT’s video for commentary and criticism. The original interview is on Starter Story. Revenue, pricing, and conversion metrics reflect the video’s period. Product features and policies are distinguished using official guidance checked on October 30, 2026.

    FAQ

    Can Vaultaire be considered an AI-built app?

    The founder says he used coding agents and did not personally write the code or website copy. That does not imply unattended development or operations without review. Product decisions and operational responsibility are separate matters.

    Is the $41,000 monthly figure recurring revenue or net profit?

    No. The video presents revenue for one specific month. It includes lifetime purchases, so it differs from MRR. It is not net profit after fees, expenses, and taxes, nor was it independently verified against accounting records.

    Will writing one AI-generated post every day improve search rankings?

    There is no guarantee. One post a day is simply the founder’s operating approach. First check the connection between search intent and product, accuracy, informational value, and differences from existing articles.

    Does Vaultaire have no external services and collect no data at all?

    That should not be assumed. Official guidance includes encrypted CloudKit backup and sharing, plus analytics and crash diagnostics enabled by default. The developer not holding readable vault contents differs from having no external services or analytics data at all.

    Original Korean article

  • What Is OpenAgents Workspace? How to Bring AI Agents Together

    What Is OpenAgents Workspace? How to Bring AI Agents Together

    You assign development to Claude Code and ask Codex for a review. Then you copy and paste material from a research agent. You have several agents, but scattered conversations and deliverables leave you acting as the go-between. OpenAgents Workspace aims to connect these distributed people and AI agents in one collaborative space.

    The OpenAgents discussed here is OpenAgents Workspace at openagents.org. It is a separate project from OpenAI Agents SDK and similarly named personal assistants or coding tools. Using its official introductory YouTube video and web documentation, we examine what it connects and how collaboration works. We also look at what to check before adopting it.

    OpenAgents Workspace Is More a Shared Workplace Than a New AI Model

    The official documentation describes OpenAgents as a platform where people and AI agents collaborate around shared conversations, files, and tasks. Its focus goes beyond displaying several agents on one screen. It emphasizes assigning requests and reviewing results in a single thread.

    You can connect agents you already use, such as Claude Code, Codex, and OpenClaw. Each agent retains its execution environment, while Workspace connects messages, shared materials, and the flow of work. It does not replace every agent with a new, single model.

    The official introductory video shows Claude Code writing code, Codex handing over an image, and OpenClaw checking the build. This demonstration illustrates the product’s workflow. It is not an independent performance test showing that every task finishes at the same speed or quality.

    Shared conversation and browser collaboration demonstration in the official OpenAgents introductory video
    Source: Official OpenAgents Workspace 1.0 introductory video, demonstration at 00:18. Frame reproduced to explain the discussion.

    The video introduces Workspace 1.0 from August 2026. The current official product page presents v1.1, so its latest feature names may differ from the video’s interface. This guide also draws on official documentation checked on October 28, 2026.

    Workspace and Launcher Serve Different Roles

    The difference between the collaborative space and the agent launcher can be confusing at first.

    Workspace: Where Conversations, Materials, and Progress Come Together

    Workspace is a collaborative space you open in a browser. Its official guide introduces Threads, Files, Knowledge, Browser, Tasks, Workflows, Routines, and Inbox. The latest v1.1 product page also emphasizes Issues and sharing and approval controls.

    Workspace is where people submit requests, agents deliver results, and reviewers leave feedback. It also offers access through desktop and mobile interfaces, not just the web.

    Launcher: Running Agents and Connecting Them to the Space

    Launcher installs, configures, and runs agents on your computer and connects them to Workspace. The documentation also describes a CLI approach for connecting remote servers. If an agent needs to handle local files, configure where it runs and which folders it can access.

    The official documentation also introduces a Cloud Agent option that requires no installation. Using Workspace therefore does not require everyone to install the same desktop app first. Deciding whether to start with a cloud agent or connect an agent on your own PC or serverfirst makes the setup clearer.

    This distinction also matters for continuous operation. Accessing Workspace from your phone does not keep a local agent working on a powered-off laptop. Long-running work requires the connected computer or server, agent process, and model service to remain available.

    Getting Started: Verify the First Response After Connecting, Not Just Space Creation

    The latest official getting-started documentation describes a hosted service accessed through a login. The basic process is as follows.

    1. Sign in and open Workspace: Sign in to your account on the official site and open your workspace.
    2. Choose where to run the agent: Decide between Cloud Agent, your local computer, and a remote server.
    3. Connect a device or agent: Follow the required steps through Connect Agent or the desktop connection screen.
    4. Complete authentication and model configuration: Check the connected agent’s provider login and API settings.
    5. Send a small request in Threads: Verify an actual response, file access, and delivery of the result.

    For example, begin by sharing one nonsensitive document. Ask the agent to separate its main points from items needing verification. An online connection indicator does not mean model calls and file operations succeed. You need to check the first result.

    The product README or early videos may still describe starting without an account. The steps here follow the current official onboarding documentation. Authentication may differ by installed version or self-hosting setup. If so, check the relevant guide.

    No OpenAgents installation was performed on the user’s PC while preparing this guide. No external Workspace was created or connected. This guide compares official videos with documentation. It is not a hands-on account of reproducing an installation in a separate environment.

    Threads, Files, and Knowledge: The Building Blocks Connecting Conversations and Materials

    The official documentation defines Threads as ongoing conversations involving both people and agents. Agents can refer to earlier thread content and build on another participant’s results.

    @claudeis one way to address a request to a specific agent. You can also divide roles among several participants. Check the agents connected to your Workspace for the names you can actually use. Typing a name does not automatically create an agent that does not exist.

    It helps to separate materials by purpose.

    • Threads: Ongoing requests, questions, decisions, and discussions of results.
    • Files: Documents needed for work and deliverables generated by agents.
    • Knowledge: Project background, rules, and decisions to reuse across conversations.
    • Inbox: Updates to check later, such as completion notifications and scheduled task results.

    Keep current project terminology and writing standards in Knowledge, and exchange drafts for individual tasks through Files. This can reduce repeated lengthy explanations. However, you must separately maintain the accuracy and currency of shared documents. If several agents use the same incorrect material, its errors can spread among them.

    OpenAgents introductory screen showing people and AI agents participating as one team
    Source: Official OpenAgents Workspace 1.0 introductory video, demonstration at 00:36. Frame reproduced to explain the discussion.

    The official introductory video also shows inviting teammates and having people and agents work in the same conversation. Rather than automation that removes people, this is better understood as collaboration where people contribute judgment when needed.

    Collaboration Means Defining Roles and Sequence, Not Just Calling Several Agents

    The official collaboration documentation introduces the following modes.

    • Dynamic: A router chooses which agent responds next based on the message.
    • Master / sub-agents: A thread leader receives requests and delegates them to other participants.
    • Workflow: Work proceeds through a saved sequence of steps.

    The latest v1.1 product guide also describes proactive and passive response options, along with separate executor and reviewer roles. Documentation terminology may differ from the product interface. Check the thread settings in your current version.

    Actual responsibility matters more than mode names. Rather than asking everyone to work things out together, define who drafts and who reviews against which criteria. Also decide what must be reported to a person.

    For example, development work could be divided as follows. This is an application example, not a reproduction of the official demo.

    1. The executor proposes the scope of changes and an implementation approach.
    2. The reviewer checks requirements, permissions, and potential errors.
    3. The executor changes only the approved scope and records test results.
    4. A person reviews the changes and unverified items, then decides whether to merge or deploy.

    Agents exchanging positive responses does not mean verification is complete. Check final results against the actual changed files, test records, and supporting documents.

    What Do Tasks, Issues, Workflows, and Routines Manage Separately?

    Managing work through conversation alone makes progress easy to lose track of. The official documentation separately describes task boards for tracking status, step-based automation, and scheduled execution.

    Tasks and Issues: Tracking Ownership and Progress

    The introductory video and documentation show work in pending, in-progress, and completed states. In the latest v1.1 guide, Issues connects assignees, participants, labels, and discussions to threads and materials.

    These features can distinguish a request mentioned in conversation from work someone owns through completion. However, a completed card must not replace verification that the actual deliverable exists and meets requirements.

    Workflows: Connecting Steps in Repeated Work

    Workflows automates sequences of steps. The official video shows an agent’s draft connected to human review and follow-up work by another participant. This structure could suit reports or reviews that follow the same sequence each time.

    OpenAgents Workflows introductory screen connecting agent work and human review
    Source: Official OpenAgents Workspace 1.0 introductory video, demonstration at 00:58. Frame reproduced to explain the discussion.

    Automation should define more than the success path. Decide where work stops and who gets notified when information is missing, reviews reject work, or execution fails.

    Routines: Repeated Execution at Scheduled Times

    Routines runs tasks on a set schedule and delivers results to a conversation or Inbox. Possible examples include summarizing customer feedback every weekday or checking materials regularly.

    Official introductory screen showing recurring task scheduling with OpenAgents Routines
    Source: Official OpenAgents Workspace 1.0 introductory video, demonstration at 00:50. Frame reproduced to explain the discussion.

    The video’s ’24/7′ wording is promotional language illustrating the intent of scheduled execution. Actual execution depends on connectivity, server availability, model limits, and task settings. It does not guarantee unlimited free execution or uninterrupted operation.

    How Could It Apply to Research and Report Writing?

    Beyond development, possible applications include work divided into collection, review, and writing roles. The following are practical suggestions, not cases with verified benefits in a particular organization.

    • Researcher: Organize official source materials, dates, and evidence suitable for citation.
    • Reviewer: Check for missing sources, outdated materials, and conflicting figures.
    • Writer: Draft the text using the reviewed materials.
    • Person: Check facts, interpretations, and what may be disclosed, then give final approval.

    Collect requests, results, and shared materials in Workspace. Keep writing rules for future tasks in Knowledge. Retain source links and the scope of verification alongside collected material. This helps prevent a researcher’s summary from being mistaken for the source itself.

    A small combination, such as a drafter and reviewer, is more realistic than connecting many agents immediately. Check for missed handoffs and review time first. More collaboration tools can also mean more changes and decisions for people to understand.

    Permissions, Data, and Costs to Check Before Adoption

    Local Execution Is Not the Same as Local Data Storage

    The official security guide states that local agents execute code on your own computer. It also says hosted servers store messages, agent responses, and related metadata. Review shared files and conversation content in light of how you use the service.

    Do not interpret ‘the agent runs locally’ as ‘no information ever leaves my PC.’ Distinguish content sent to the model, materials uploaded to Workspace, and recipients of external sharing.

    The official messaging documentation also describes public snapshot links for conversations. Before creating a shared link, check for secrets, customer materials, and internal decisions.

    Check Team Sharing and Agent Execution Permissions Separately

    The latest v1.1 guide emphasizes private-by-default agents and devices, explicit access grants, and approvals for agent use or actions. Inviting someone to the same Workspace does not automatically share access to every device and agent.

    Conversely, separating access in the interface does not establish operating-system isolation for running agents. Check the connected runtime’s file and shell permissions and approval policies. Some listed agents are in Beta or still undergoing real model-integration verification. Do not assume all have the same verification level.

    Separate Free Entry from Total Operating Costs

    The official site says you can start for free. However, check model API, existing agent subscription, remote server, and browser costs separately. Also distinguish how keys supplied to cloud agents are handled from keys used in local Launcher.

    An open-source platform does not make all connected models and external services free. Before enabling recurring tasks, define their frequency and how retries and notifications work after failures.

    Self-Hosting Does Not Automatically Block External Data Transfers

    OpenAgents describes self-hosting under Apache 2.0. Organizations seeking to manage the collaboration server and data on their own infrastructure can consider this option.

    However, even a self-operated server may send relevant information to external model APIs or other external services. Self-hosting, isolated-network operation, and local model execution are not the same. Design the data flows separately.

    When Is It Worth Considering?

    OpenAgents Workspace may be worth examining when several agents and people need shared materials, draft-review exchanges, and recurring task tracking. Conversely, a collaboration platform may add unnecessary administration for simple solo questions or work handled by one agent.

    The key criteria are not how many tools can connect, but whether materials and results become less scattered, approval responsibilities become clearer, and actual deliverables become easier to verify. Start with a small private task and check these conditions before expanding its use.

    Related Reading

    FAQ

    Are OpenAgents Workspace and OpenAI Agents SDK the Same?

    No. This guide covers the collaboration platform at openagents.org. Despite the similar name, it is a separate project from OpenAI Agents SDK. It focuses on connecting existing agents in a space where they work alongside people.

    Must I Install Launcher to Use Workspace?

    Not always. The official documentation explains how to start with Cloud Agent. To connect a local agent handling PC files or a remote device, check the relevant Launcher or CLI connection process.

    Do Scheduled Tasks Keep Running When My PC Is Off?

    A local agent cannot keep running on a powered-off PC. Scheduled work requires the server or device running the agent and the model service to remain available. Workspace accessibility and agent availability are separate matters.

    Does Self-Hosting Keep All Data from Leaving the System?

    Not automatically. Managing the Workspace server yourself differs from controlling data sent to models and external services. Check the full route, including the models and connected tools you use.

    References

    The images are captures used to explain and critique features and demonstrations in the official introductory video. Video demonstrations, current documentation, and this guide’s application suggestions are distinguished. They do not indicate that an independent installation reproduction, performance test, or security audit was completed.

    Original Korean article

  • Cognitive Debt in AI Coding: What to Check Before Orca and Buzz

    Cognitive Debt in AI Coding: What to Check Before Orca and Buzz

    AI writes the code, another AI reviews it, and they even submit a PR. Work appears faster. But what remains if a person cannot explain why the changes were made or what they affect? Cognitive debt in AI coding is the gap between code generation speed and human understanding.

    Modu AI’s video reviewing Orca and Buzz addresses this problem. It does not conclude that either tool is bad. The creator acknowledges the potential of collaborative approaches but warns against expanding delegation before developing the ability to understand and control a single agent’s results. That makes it worth focusing on what developers should verify, rather than competition over tool features.

    Orca and Buzz May Be Convenient, but Review Responsibility Remains

    The video presents Orca as connecting multiple coding agents and models in one workspace. It presents Buzz as a channel-based setting where people and agents converse together. The creator describes having another model review work, assigning development roles, and receiving a PR.

    Video comparing agent collaboration approaches in Orca and Buzz
    Source: Modu AI, source video at 01:35. Frame reproduced to explain the discussion.

    This is not an independent comparison of the two products’ latest specifications and performance. Promotional claims shown onscreen, such as productivity multipliers, are not cited as measured results. The focus is not the interface. It is who understands and approves results once delegation becomes easier.

    Having one AI ask another AI for a review does not establish that the review was independent or sufficient. They may have accepted the same assumptions, missed the same materials, or failed to test important failure conditions. Switching models can provide a different perspective. It does not prove that errors have been eliminated.

    The creator says the PR produced by several agents was satisfactory. Yet the creator also describes difficulty following the changed files and decisions. These observations are not contradictory. A plausible result and understanding it well enough to take responsibility for fixing it are different states.

    Cognitive Debt Means Putting Off the Work of Understanding

    In the video, cognitive debt is the burden that accumulates when understanding AI’s work is postponed. You may move on because the interface looks normal. But an incident or further development could force you to learn the structure from scratch later.

    This is not a formal metric measured here or a diagnosis applying to every AI user. It is a perspective for examining gaps in understanding during development. Consider the following situations.

    • A feature works, but you cannot readily explain which data and files it passes through.
    • You read AI’s summary but did not check whether it matches the actual changes.
    • Review comments were resolved, but you do not know which tests support those resolutions.
    • You cannot readily identify what to roll back after a problem or whether the data can also be restored.

    The point is not to memorize all the code. The creator does not argue that building a product requires reading every line. What matters is understanding enough to assess change scope and key connections as the system grows, and to recover from problems.

    What Else Should You Check as Agent Numbers Grow?

    The video shows a diagram of increasing possible relationships between agents. If every agent is paired with every other agent, without distinguishing direction, the number of possible relationships is n(n-1)/2. Under this assumption, 3 agents yield 3 pairs, 4 yield 6 pairs, and 6 yield 15 pairs.

    Video diagram explaining the number of possible relationships between agents
    Source: Modu AI, source video at 12:15. Frame reproduced to explain the discussion.

    However, this formula counts possible connections. It does not mean actual message volume or review costs must reach those numbers. The relationship count is quadratic, not mathematical proof of exponential growth. Actual overhead depends on whether there is a central coordinator and who passes results to whom.

    In practice, the following questions are more useful than asking how many agents were added.

    1. Do participants’ change scopes overlap?
    2. What supporting evidence accompanies one participant’s results when passed to the next?
    3. When opinions conflict, who decides, and by what criteria?
    4. Can the final PR’s actual changes be compared with what was agreed?
    5. Are test failures and uncertainties reported to a person?

    Checking these points does not require reading every conversation or private internal reasoning. What you should request is the reasons for changes, reviewable evidence, impact scope, execution results, and unverified items. A short decision record linked to the actual diff and tests may help more than a lengthy discussion transcript.

    A Visible Collaboration Interface Is Not the Same as Understood Results

    The Buzz walkthrough shows creating a channel, inviting agents, and conversing with them. Seeing who is responding and in which role may help you follow the collaboration process.

    Buzz walkthrough showing creation of a channel for agents to join
    Source: Modu AI, source video at 05:50. Frame reproduced to explain the discussion.

    However, seeing a conversation differs from understanding the effects of actual code. Several agents may respond positively while collectively missing an important failure condition. A generated PR does not mean the work is ready for deployment.

    A final report should go beyond summarizing the conversation and cover the following items.

    • What changed: Features and major changed files.
    • Why it changed: Requirements and the rationale for the choices.
    • What it affects: Called functionality, data, permissions, and external integrations.
    • What was verified: Tests executed and their actual results.
    • What remains: Unverified conditions and items requiring approval.

    This list does not reproduce the video’s implementation. It is a suggestion for applying its concerns to practical review.

    A Teach-Back Hook: Asking What You Understand Before a Commit

    The creator describes building a hook that checks understanding before commits to reduce cognitive debt. Initially, users had to explain the changes themselves. Later, the process allowed commits after passing multiple-choice questions. The video also introduces an HTML walkthrough that explains incorrect answers and checks understanding again.

    Concept diagram of pre-commit comprehension questions and a teach-back hook
    Source: Modu AI, source video at 18:05. Frame reproduced to explain the discussion.

    The useful idea is incorporating the intention to understand into the work process, rather than postponing it. However, the video’s description does not verify implementation code, check coverage, bypass prevention, or control over every commit path. Do not interpret the quiz as a built-in Claude Code feature.

    According to the official documentation, Claude Code hooks and Git pre-commit hooks are different systems. Claude Code hooks automate actions at particular events, such as session events or tool calls. Git hooks are separate mechanisms triggered by Git operations. Coverage depends on which conditions are connected to which system.

    Rather than assuming a hook completely blocks commits, check which execution paths it inspects and when it fails or permits execution. Do not treat a single local hook as equivalent to server-side approval rules or a security boundary.

    Correct Quiz Answers Do Not Guarantee Code Safety

    Comprehension questions can prompt a review. But their value weakens if AI-generated questions and answers are wrong, users merely memorize answers, or code changes after the questions.

    If applying this approach yourself, consider the following design choices. These are suggestions for improvement, not code reproducing the creator’s hook.

    • Tie questions to the changes under review. If those changes differ, reassess the previous pass status.
    • Ask about impact scope, failure conditions, and recovery methods, not just recall of code content.
    • When explaining correct answers, check the actual changes and test evidence together.
    • Even after a comprehension check passes, review tests, permissions, and data protection separately.
    • If an urgent exception is needed, record what was skipped and who is responsible for follow-up verification.

    For example, asking only for the name of a modified function may be less useful than asking about failure consequences. Having users explain which user flows would be affected and how to verify them may better serve a real review.

    What Coding-Learning Research Supports—and What It Does Not

    In research released in January 2026, Anthropic tested 52 software developers, mostly juniors, learning a new Python library, Trio. Its official overview reports average quiz scores of 50% for the AI group and 67% for those coding themselves. The difference in task completion time was not statistically significant.

    The researchers also discuss differences between simply receiving generated code and building understanding through follow-up questions, explanations, and conceptual checks. However, qualitative analysis of interaction types must not be treated as proof of a particular learning method’s causal effects.

    These results concern a specific task involving learning a new library. The experiment did not compare Orca with Buzz or measure multi-agent performance. It cannot support broader conclusions that AI reduces every developer’s understanding or that multiple agents lower productivity.

    The connection to the video’s concerns is narrow and clear. Completing a task and developing understanding during it need to be checked separately.

    Five Checks Before Adding More Agents

    You do not need perfect control over one agent before taking the next step. But before expanding delegation, check whether you can answer the following questions about your current work.

    1. Purpose: Can you explain the user problem this change is intended to solve?
    2. Scope: Can you identify the main changed files and connected features?
    3. Evidence: Can you compare key implementation and review decisions against actual changes and requirements?
    4. Verification: What was tested, and what remains unverified?
    5. Recovery: If something goes wrong, which code, settings, and data must you inspect and restore?

    If these questions are hard to answer, consider smaller tasks, narrower PRs, and clearer change explanations before adding agents. Conversely, if roles are clear and results can be independently checked, expand parallel work where needed.

    This single video cannot determine the optimal number of agents. The important criterion is not how many are working, but whether a person can understand and approve the results, then fix them when necessary.

    Related Reading

    FAQ

    Must I Read All AI-Written Code to Resolve Cognitive Debt?

    The point is not to memorize every line. It is to understand enough to judge key change rationales, impact scope, verification evidence, and recovery methods if something fails.

    Does This Mean I Should Not Use Orca or Buzz?

    No. The creator acknowledges both tools’ potential and strengths. It is better understood as experience-based advice against expanding collaboration while a single agent’s results remain difficult to understand.

    Does Claude Code Require Passing a Comprehension Quiz Before Committing by Default?

    The video describes a hook and walkthrough approach built by the creator. The quiz should not be considered a default feature. Its actual implementation and check coverage also require separate verification.

    Can I Skip Human Review After Passing an AI Review?

    Passing an AI review alone does not guarantee safety or compliance with requirements. Define the scope of human approval using actual changes, tests, permission and data impacts, and unverified items.

    References

    The images are captures used to explain and critique the source video’s discussion. The creator’s personal experience, official technical documentation, a learning experiment under specific conditions, and this guide’s practical suggestions are distinguished. They do not indicate a completed product-performance comparison or independent execution and security verification of the hook.

    Original Korean article

  • Create AI HTML Slides with ChatGPT, Claude, and Motion Graphics

    Create AI HTML Slides with ChatGPT, Claude, and Motion Graphics

    Some presentations change their charts when you click a year. Others open detailed explanations when you select an item. Instead of advancing through slides, they show information on one screen in response to questions. These are HTML slides. Think of them as small, interactive web pages used for presentations.

    Aker’s video shows how to draft slides with ChatGPT and Claude, revise the content, and add motion graphics. The priority is not cramming in effects. A usable result requires accurate information, saved edits, and reliable operation in the actual presentation environment.

    HTML slide demonstration with financial charts that change according to the selected year
    Source: Aker video, 00:10. A UI demonstration linking charts by year. The company figures shown are not independently verified financial data. Scene quoted for commentary and criticism.

    When are HTML slides useful?

    HTML slides use HTML to structure content, CSS to define its appearance, and JavaScript to connect clicks with on-screen changes. Charts, text, and images can change together based on the presenter’s selection. Detailed panels can also open over the main content.

    Consider them for meetings focused on customer-selected specifications, reports comparing performance by year or field, or training that changes sequence with questions. However, required submission formats such as PPTX or PDF take priority. Creating an HTML file does not automatically produce a submission-ready PPTX.

    The Tesla material in the video demonstrates functionality. This is not a company analysis comparing the displayed financial figures or vehicle specifications against official sources. Avoid copying those numbers directly into work materials.

    Separate source materials, design references, and operating requirements before starting

    The video gathers source materials and design references in a folder, then connects it to AI. Distinguish their roles when preparing your materials.

    • Source materials: Files used to verify the actual content, such as reports, tables, and explanatory documents. Clearly identify each figure’s year, unit, and source.
    • Design references: Guidelines for colors, layout, and emphasis. Keep them separate so reference-screen text and figures are not mistaken for factual source material.
    • Fonts and images: Check the usage and distribution terms for your chosen fonts and images. Appearing in free search results does not imply permission for every use.
    • Presentation requirements: Decide the aspect ratio, internet access, audience devices, submission format, and scope of information that may be disclosed in advance.

    The video description provides the original master prompt and reference links. The examples below are not verbatim copies. They are revised requests with additional saving, review, and distribution requirements.

    ChatGPT and Claude have different interfaces

    The video uses Sites in ChatGPT Work and Claude’s working-folder connection. Its model names and reasoning settings reflect choices made at the time. That combination is not necessarily available to every account or always the best option.

    OpenAI’s official Sites guidance says sites can be created in Work on the web, or in Work or Codex in the desktop app. There is no need to assume that making HTML slides always requires installing a desktop app. However, directly using a specific folder on your PC differs from attaching materials on the web.

    Claude’s official Cowork guidance also distinguishes working environments and conditions for local file access. Connecting a folder does not mean all AI processing stays on your PC. Before supplying sensitive materials, check the limits allowed by your service and organization.

    Also, a freely available prompt is not the same as a service you can run for free. Check your account’s current terms for available features and usage limits.

    Step 1: Structure the content before adding effects

    Start by defining the presentation’s purpose and each slide’s message. Requesting every animation and linked interaction at once makes problems harder to diagnose.

    The following sample request is for an education program briefing. It assumes no actual case or performance figures from any particular institution.

    Create an HTML presentation for an education program briefing using the attached source materials.
    The audience consists of practitioners encountering this information for the first time. Use around 7 slides.
    
    First propose each slide's key message and supporting evidence, then implement it.
    Include each figure's original year, unit, and source. Do not invent missing values.
    Use the design references only as guidelines for colors and layout.
    
    Make the body text easy to read. Avoid excessive breaks within Korean words.
    Make the key information understandable even without using interactions.
    List dependencies on external fonts, libraries, and images, along with the files required to run the presentation.
    

    Review the draft for overlapping slide messages, overcrowded slides, and missing sources or units. Fixing these issues comes before making inaccurate material move impressively.

    Step 2: Distinguish on-screen editing from saving files

    The video demonstrates an editing mode that lets you click text and change it directly. Requesting this feature reduces the need to issue a chat instruction for every wording change.

    Editing mode for changing HTML slide text directly on screen
    Source: Aker video, 06:16. The video’s text-editing interface. Browser editing and permanent file saving require separate checks. Scene quoted for commentary and criticism.

    However, changing text in the browser differs from saving it to the original HTML file. MDN’s contenteditable documentation covers the attribute that makes elements editable. Adding that attribute alone does not create a file-saving feature.

    When requesting an editing mode, specify how changes should be saved as well.

    Add an editing mode that lets me change text directly.
    
    Distinguish the content being edited from the file to be distributed.
    After editing, let me export the final HTML with all changes included.
    Provide a procedure for checking that the text remains changed after reopening the exported file.
    Hide editing buttons and input areas in presentation mode.
    

    Saving to the browser’s localStorage is not the same as exporting a file. MDN explains that behavior in a file: environment, where files are opened directly, can vary between browsers. Check for yourself whether edits remain when you move the same file to another PC.

    The check is simple. Edit the text, save or export the final version, close the window, and reopen that file. Also check that the distribution includes all required reference images and videos.

    Step 3: Define selections, changes, and evidence together

    The video’s linked effects change related information when a year or lever is selected. What matters is not the lever itself, but which selection changes which data and explanation.

    HTML slide with images and explanations that change when a lever is selected
    Source: Aker video, 08:00. An example of a linked UI in the video. The displayed vehicle specifications have not been verified against official specifications. Scene quoted for commentary and criticism.

    You can request behavior and review requirements together, as follows.

    When a year from the source materials is selected, update the chart, summary text, and units together on the same slide.
    Clearly show the selected year. Mark values without supporting data as requiring verification.
    Do not arbitrarily change chart axes or comparison baselines.
    
    Allow selection using a keyboard and touch as well as a mouse.
    Keep the data and key explanations readable when motion is disabled.
    

    Animated numbers also need review. Check that their final values match the source materials and that chart axes do not exaggerate small differences. Animation options in tools such as Chart.js control presentation; they do not guarantee data accuracy.

    The same applies to detail panels. Define which item opens what, how it closes, and whether closing it restores the original context. If important information appears only on hover, test its usability on touch devices and with presentation controls.

    For motion graphics, distinguish HTML animations from video files

    The video shows a workflow of providing a reference video, specifying a topic and duration, and adding the resulting motion graphics to slides.

    Request specifying the placement and title of motion graphics on the final slide
    Source: Aker video, 11:50. A sample request specifying where motion graphics should appear and their title. This does not prove that every tool automatically generates an MP4. Scene quoted for commentary and criticism.

    First decide the output format. Distinguish an animated scene running in a browser from an MP4 playable in other programs. A moving code preview is not the same as an actual video file.

    The following request also specifies the output format.

    Create a short animated scene summarizing the presentation's key message.
    Use the reference video only for transitions and rhythm. Do not directly copy its distinctive images, logos, or audio.
    
    First state whether the output is an HTML animation or a video file.
    If providing an MP4, include the file and its playback requirements.
    Place it on the presentation's final slide and provide play and pause buttons.
    If autoplay is blocked, allow playback to start with a click.
    

    Browser autoplay policies may block media, particularly media with sound. MDN also explains restrictions on audible media and how user interaction affects playback. Providing manual playback controls is safer than assuming the page will automatically play sound when opened.

    What reliable fonts and offline operation actually require

    HTML can open on many devices, but environmental differences do not disappear automatically. If web fonts, external images, or chart libraries load from the internet, losing connectivity may change the result.

    For offline use, bundle the required assets and check whether you may embed and distribute the fonts. Specify fallback fonts for cases where the chosen font fails to load. Finally, disconnect the actual presentation PC from the network and test the file.

    Do not assume confidential materials are safe simply because the output is a local HTML file. Check for remaining external scripts and requests, and inspect the included data. Separately review what you supply during generation and what communicates externally when the finished file runs.

    Open shared links with another account before presenting

    The video shows two access methods: opening files directly and using shared links. Test either method under the actual recipient’s conditions.

    Claude’s current official guidance distinguishes access requirements by how Artifacts are created and shared. New Artifacts and legacy artifacts have different publishing methods. Login requirements and organization settings also matter. Not every shared link is a page anyone can open without an account just by knowing its address.

    Before presenting, test with another account or an incognito window, not just your own logged-in browser. For internal materials, use approved transfer and storage methods rather than creating public links.

    Six checks before your final presentation

    1. Content: Do numbers, years, units, and sources match the source materials?
    2. Saving: Do edits remain when you reopen the final exported file?
    3. Controls: Are key functions accessible by clicking, keyboard, and touch?
    4. Operation: Do fonts, charts, and videos work on the actual presentation PC under its network conditions?
    5. Sharing: Does the recipient have the necessary permissions, and is any information unnecessarily public?
    6. Submission: If PDF or PPTX is required, have you reviewed a separate deliverable in that format?

    The advantage of HTML slides is less about movement than adjusting the depth of an explanation to the questions asked. Presentations are fundamentally about communication. Choose the features needed to convey your message instead of adding every effect.

    Related reading

    References

    Images in this article quote explanatory and demonstration scenes from Aker’s video for commentary. The video’s workflow, official documentation requirements, and the practical requests supplemented here are distinguished from one another. Official guidance was checked as of November 1, 2026. This was not an experiment independently recreating the same slides to compare tool performance.

    FAQ

    Do I need to learn coding to make HTML slides?

    You can describe the structure and behavior to AI and request a draft. You still need to check the output’s data, saving, sharing, and operating requirements. Starting with a static draft and adding one feature at a time makes review easier.

    Does HTML guarantee reliable fonts and operation without internet access?

    No. Check external font, image, and library dependencies. Include the required assets, then open the file offline in the actual environment. Also check font embedding and distribution terms.

    Does changing text on screen also save it to the original file?

    That depends on how editing is implemented. Distinguish on-screen changes, browser storage, and exporting updated HTML. Verify the result by reopening the final file after saving.

    Can HTML slides completely replace PowerPoint?

    Choose based on the situation. They are worth considering for interactive meetings. However, if an institution or customer requires PPTX or PDF, you need a separate deliverable in that format and a review.

    Original Korean article

  • AI HTML 슬라이드 만들기: ChatGPT·Claude와 모션그래픽 활용법

    AI HTML 슬라이드 만들기: ChatGPT·Claude와 모션그래픽 활용법

    연도를 누르면 그래프가 바뀌고, 항목을 선택하면 상세 설명이 열리는 발표 자료가 있다. 장표를 계속 넘기는 대신 한 화면에서 질문에 맞춰 정보를 보여주는 HTML 슬라이드다. 브라우저에서 움직이는 작은 웹페이지를 발표 자료로 쓰는 방식이라고 이해하면 쉽다.

    Read in English

    에이커의 영상은 ChatGPT와 Claude로 초안을 만들고, 내용을 수정한 뒤 모션그래픽을 더하는 과정을 보여준다. 따라 할 때 중요한 것은 효과를 많이 넣는 일이 아니다. 자료의 정확성, 편집한 내용의 저장, 실제 발표 환경에서의 실행까지 연결해야 쓸 수 있는 결과물이 된다.

    선택한 연도에 따라 재무 차트가 바뀌는 HTML 슬라이드 시연
    출처: 에이커 영상 00:10. 연도별 차트를 연결한 영상 속 UI 시연. 화면의 기업 수치는 독립 검증한 재무자료가 아니다. 해설·비평 목적의 장면 인용.

    HTML 슬라이드는 언제 유용한가

    HTML 슬라이드는 HTML로 내용을 구성하고, CSS로 모양을 정하며, JavaScript로 클릭과 화면 변화를 연결한다. 발표자가 선택한 조건에 따라 차트·문구·이미지를 함께 바꾸거나, 본문 위에 상세 패널을 띄우는 식으로 만들 수 있다.

    고객이 관심 있는 사양을 골라 설명해야 하는 미팅, 연도·분야별 실적을 비교하는 보고, 질문에 따라 순서를 바꾸는 교육에서 검토할 만하다. 반면 제출 형식이 PPTX나 PDF로 정해져 있다면 그 요건이 먼저다. HTML 파일을 만들었다고 제출 가능한 PPTX가 함께 생기는 것은 아니다.

    영상에 나오는 테슬라 자료는 기능을 설명하는 시연 화면이다. 이 글은 화면 속 재무 수치나 차량 사양을 공식 자료와 대조한 기업 분석이 아니므로, 해당 숫자를 업무 자료에 그대로 옮겨 쓰지 않는 편이 좋다.

    시작 전에는 자료·디자인·실행 조건을 나눈다

    영상은 원천자료와 디자인 레퍼런스를 폴더에 모은 뒤 AI에 연결한다. 자료를 준비할 때는 역할을 구분하는 것이 좋다.

    • 원천자료: 보고서·표·설명 문서 등 실제 내용을 확인할 파일이다. 수치의 연도·단위·출처를 분명하게 둔다.
    • 디자인 참고자료: 색상·배치·강조 방식의 기준이다. 참고 화면의 문구나 수치를 사실 자료처럼 사용하지 않도록 구분한다.
    • 폰트와 이미지: 사용할 글꼴과 이미지의 이용·배포 조건을 확인한다. 무료 검색 결과라는 이유만으로 모든 용도를 허용한다고 판단하지 않는다.
    • 발표 조건: 화면 비율, 인터넷 연결, 청중의 기기, 제출 형식, 공개 가능한 정보의 범위를 미리 정한다.

    영상 설명란에는 원본 마스터 프롬프트와 참고 링크가 공개돼 있다. 아래 예시는 그 문구를 그대로 옮긴 것이 아니라, 저장·검수·배포 조건을 보강해 재구성한 요청안이다.

    ChatGPT와 Claude의 화면은 같지 않다

    영상에서는 ChatGPT Work의 Sites와 Claude의 작업 폴더 연결 방식을 사용한다. 모델 이름과 추론 설정은 영상 당시의 선택이다. 그 조합이 모든 계정에서 제공되거나, 언제나 가장 좋은 결과를 낸다는 뜻은 아니다.

    OpenAI의 공식 Sites 안내는 웹의 Work와 데스크톱 앱의 Work 또는 Codex에서 사이트를 만들 수 있다고 설명한다. 따라서 HTML 슬라이드를 만들려면 무조건 데스크톱 앱을 설치해야 한다고 일반화할 필요는 없다. 다만 내 PC의 특정 폴더를 직접 활용하는 방식과, 웹에서 자료를 첨부하는 방식은 구분해야 한다.

    Claude도 공식 Cowork 안내에서 작업 환경과 로컬 파일 접근 조건을 나눠 설명한다. 연결한 폴더를 쓴다고 AI 작업 전체가 내 PC 안에서만 처리되는 것은 아니다. 민감한 자료는 사용 중인 서비스·조직의 허용 범위를 먼저 확인하자.

    또한 무료로 제공되는 프롬프트와 무료로 실행할 수 있는 서비스는 다른 문제다. 실제 이용 가능 기능과 사용량은 계정의 현재 조건을 확인해야 한다.

    1단계: 효과보다 내용 구조를 먼저 만든다

    초안에서는 발표 목적과 장표별 메시지를 먼저 정한다. 처음부터 모든 모션과 연동 기능을 한 번에 요구하면 무엇이 잘못됐는지 찾기 어려워진다.

    다음은 교육사업 설명회를 예로 든 요청안이다. 특정 기관의 실제 사례나 성과 수치를 전제하지 않는다.

    첨부한 원천자료로 교육사업 설명회용 HTML 발표 자료를 구성해 줘.
    청중은 처음 내용을 접하는 실무자이며, 7장 안팎으로 정리해 줘.
    
    먼저 각 장의 핵심 메시지와 사용할 근거를 제안한 뒤 구현해 줘.
    수치에는 원본의 연도·단위·출처를 붙이고, 없는 값은 만들지 말아 줘.
    디자인 참고자료는 색상과 배치의 기준으로만 사용해 줘.
    
    본문을 읽기 쉬운 크기로 배치하고 한글 단어가 과도하게 끊기지 않게 해 줘.
    인터랙션을 사용하지 않아도 핵심 내용을 이해할 수 있게 해 줘.
    외부 폰트·라이브러리·이미지 의존성과 실행에 필요한 파일을 알려 줘.
    

    초안이 나오면 장표별 메시지가 겹치는지, 한 장에 내용이 몰렸는지, 출처와 단위가 빠졌는지를 본다. 오류가 있는 자료를 화려하게 움직이게 만드는 것보다 이 단계의 수정이 우선이다.

    2단계: 화면 편집과 파일 저장을 구분한다

    영상은 글자를 직접 클릭해 바꾸는 편집 모드를 시연한다. 이런 기능을 요청하면 문구를 고칠 때마다 대화창에 지시할 필요가 줄어든다.

    HTML 슬라이드의 글자를 화면에서 직접 바꾸는 편집 모드
    출처: 에이커 영상 06:16. 영상 속 텍스트 편집 화면. 브라우저 편집과 파일의 영구 저장은 별도로 확인해야 한다. 해설·비평 목적의 장면 인용.

    다만 브라우저에서 글자가 바뀌는 것과 원본 HTML 파일에 저장되는 것은 별개다. MDN의 contenteditable 설명은 요소를 편집할 수 있게 하는 속성을 다룬다. 그 속성을 넣는 것만으로 파일 저장 기능까지 생기는 것은 아니다.

    따라서 편집 모드를 요청할 때는 저장 방식도 함께 지정하는 편이 좋다.

    문구를 직접 바꿀 수 있는 편집 모드를 추가해 줘.
    
    편집 중인 내용과 배포할 파일을 구분해 줘.
    수정이 끝나면 변경 내용을 포함한 최종 HTML을 내보낼 수 있게 해 줘.
    내보낸 파일을 새로 열어도 문구가 유지되는지 확인할 절차를 알려 줘.
    발표 모드에서는 편집 버튼과 입력 영역을 숨겨 줘.
    

    브라우저의 localStorage에 저장하는 방식도 파일 내보내기와 같지는 않다. MDN은 파일을 직접 여는 file: 환경에서 동작이 브라우저마다 달라질 수 있다고 설명한다. 같은 파일을 다른 PC로 옮겨 열 때도 수정 내용이 남는지 직접 확인해야 한다.

    검수는 단순하다. 문구를 고치고, 최종본을 저장하거나 내보낸 뒤, 창을 닫고 그 파일을 다시 연다. 배포할 파일과 참고 이미지·영상이 모두 포함돼 있는지도 함께 본다.

    3단계: 연동 효과는 선택·변화·근거를 함께 지정한다

    영상의 연동 효과는 연도나 레버를 선택하면 관련 정보가 바뀌는 방식이다. 중요한 것은 레버 자체가 아니라 어떤 선택이 어떤 데이터와 설명을 바꾸는지다.

    레버 선택에 따라 이미지와 설명이 바뀌는 HTML 슬라이드
    출처: 에이커 영상 08:00. 영상 속 연동 UI 예시. 화면의 차량 사양을 실제 공식 사양으로 확인한 자료는 아니다. 해설·비평 목적의 장면 인용.

    다음처럼 동작과 검수 조건을 함께 요청할 수 있다.

    원천자료에 있는 연도를 선택하면 같은 장의 차트·요약 문구·단위가 함께 바뀌게 해 줘.
    선택된 연도를 명확하게 표시하고, 자료가 없는 값은 확인 필요로 표시해 줘.
    차트의 축과 비교 기준을 임의로 바꾸지 말아 줘.
    
    마우스뿐 아니라 키보드와 터치로도 선택할 수 있게 해 줘.
    모션을 꺼도 데이터와 핵심 설명은 읽을 수 있게 해 줘.
    

    수치를 움직이게 만드는 효과도 검수 대상이다. 애니메이션이 끝난 최종 값이 원천자료와 일치하는지, 작은 차이를 과장하는 축을 쓰지 않았는지 확인하자. Chart.js 같은 차트 도구의 애니메이션 옵션은 표현 방식이지 데이터 정확성을 보증하는 기능이 아니다.

    상세 패널도 마찬가지다. 어느 항목을 누르면 무엇이 열리는지, 어떻게 닫는지, 닫은 뒤 원래 맥락으로 돌아오는지를 정한다. 마우스를 대야만 중요한 정보가 나오는 구성은 터치 기기나 발표용 조작 환경에서도 쓸 수 있는지 확인해야 한다.

    모션그래픽은 HTML 애니메이션과 영상 파일을 구분한다

    영상은 참고 영상을 보여주고 주제와 길이를 지정한 뒤, 만들어진 모션그래픽을 슬라이드에 추가하는 흐름을 소개한다.

    모션그래픽을 마지막 슬라이드에 넣도록 위치와 제목을 지정하는 요청
    출처: 에이커 영상 11:50. 모션그래픽 삽입 위치·제목을 지정하는 영상 속 요청 예시. 모든 도구에서 MP4가 자동 생성된다는 증거는 아니다. 해설·비평 목적의 장면 인용.

    여기서 먼저 정할 것은 산출물의 형식이다. 브라우저에서 실행되는 애니메이션 장면인지, 다른 프로그램에서도 재생할 MP4 파일인지 구분해야 한다. 코드가 움직이는 미리보기가 나온 것과 영상 파일이 실제로 만들어진 것은 같지 않다.

    아래는 결과 형식까지 명시하는 요청안이다.

    발표의 핵심 메시지를 요약하는 짧은 모션 장면을 만들어 줘.
    참고 영상에서는 화면 전환과 리듬만 참고하고 고유 이미지·로고·음원을 그대로 복제하지 말아 줘.
    
    결과물이 HTML 애니메이션인지 영상 파일인지 먼저 밝혀 줘.
    MP4로 제공한다면 파일과 재생 조건을 함께 알려 줘.
    발표 자료의 마지막 장에 넣고 재생·일시정지 버튼을 제공해 줘.
    자동재생이 차단되면 눌러서 시작할 수 있게 해 줘.
    

    특히 소리가 있는 미디어는 브라우저의 자동재생 정책에 막힐 수 있다. MDN도 유음 미디어의 자동재생 제한과 사용자 조작에 따른 차이를 설명한다. ‘페이지가 열리면 소리까지 자동으로 나온다’는 전제보다 수동 재생 수단을 함께 두는 편이 안전하다.

    폰트가 안 깨지고 오프라인에서도 된다는 말의 조건

    HTML은 여러 기기에서 열 수 있지만, 환경 차이가 자동으로 사라지지는 않는다. 웹폰트·외부 이미지·차트 라이브러리를 인터넷에서 불러오면 연결이 끊겼을 때 결과가 달라질 수 있다.

    오프라인 사용을 원한다면 필요한 자산을 함께 묶고, 폰트를 포함·배포할 수 있는지 확인해야 한다. 폰트를 불러오지 못했을 때 쓸 대체 글꼴도 정한다. 최종적으로는 실제 발표 PC에서 네트워크를 끊고 열어보는 검수가 필요하다.

    로컬 HTML 파일이라는 이유만으로 기밀 자료가 안전하다고 단정해서도 안 된다. 외부 스크립트와 요청이 남아 있는지, 포함된 데이터가 무엇인지 확인해야 한다. 생성 단계의 자료 제공 범위와 완성본을 실행할 때의 통신은 별도로 살펴보자.

    공유 링크는 발표 전에 다른 계정으로 열어본다

    영상은 파일을 직접 열거나 공유 링크로 접근하는 두 가지 방식을 보여준다. 둘 중 무엇이든 실제 수신자 조건에서 확인해야 한다.

    Claude의 현재 공식 안내는 Artifacts의 생성 방식과 공유 유형에 따라 접근 조건을 나눈다. 새 Artifacts와 legacy artifact의 공개 방식이 같지 않으며, 로그인과 조직 설정의 영향도 있다. 모든 공유 링크를 ‘주소만 알면 계정 없이 누구나 열 수 있는 페이지’로 이해하면 안 된다.

    발표 전에는 본인이 로그인한 창만 보지 말고, 다른 계정이나 시크릿 창에서 열어보자. 사내 자료라면 공개 링크를 만드는 대신 승인된 전달·저장 방식을 사용해야 한다.

    최종 발표 전 확인할 여섯 가지

    1. 내용: 숫자·연도·단위·출처가 원문과 맞는가.
    2. 저장: 편집 후 내보낸 최종 파일을 다시 열어도 수정이 남는가.
    3. 조작: 클릭·키보드·터치에서 주요 기능을 사용할 수 있는가.
    4. 실행: 실제 발표 PC와 네트워크 조건에서 폰트·차트·영상이 나오는가.
    5. 공유: 수신자에게 필요한 권한이 있고, 불필요하게 공개된 정보는 없는가.
    6. 제출: 요구하는 PDF·PPTX가 있다면 해당 형식의 별도 결과물을 검수했는가.

    HTML 슬라이드의 장점은 움직임 자체보다 질문에 맞춰 설명의 깊이를 조절할 수 있다는 데 있다. 발표 자료의 본질은 소통이다. 효과를 모두 넣기보다 메시지를 이해시키는 데 필요한 것부터 선택하자.

    함께 읽으면 좋은 글

    참고자료

    본문 이미지는 에이커 영상의 설명·시연 장면을 해설 목적으로 인용했다. 영상의 작업 흐름과 공식 문서의 조건, 이 글에서 보강한 실무 요청안을 구분했다. 공식 안내 확인 기준일은 2026년 11월 1일이며, 동일한 슬라이드를 독립 제작해 도구별 성능을 비교한 실험은 아니다.

    FAQ

    HTML 슬라이드를 만들려면 코딩을 배워야 하나요?

    AI에 구성과 동작을 설명해 초안을 요청할 수 있다. 다만 결과물의 데이터·저장·공유·실행 조건을 확인하는 책임까지 없어지지는 않는다. 처음에는 정적 초안을 만든 뒤 한 가지 기능씩 추가하는 편이 검수하기 쉽다.

    HTML이면 폰트가 깨지지 않고 인터넷 없이 실행되나요?

    자동으로 보장되지 않는다. 외부 폰트·이미지·라이브러리 의존성을 확인하고, 필요한 자산을 포함한 뒤 실제 환경에서 오프라인으로 열어봐야 한다. 폰트의 포함·배포 조건도 확인해야 한다.

    화면에서 글자를 고치면 원본 파일에도 저장되나요?

    편집 기능의 구현에 따라 다르다. 화면 수정만 되는지, 브라우저에 저장하는지, 변경된 HTML을 내보내는지 구분해야 한다. 저장 후 최종 파일을 다시 여는 방법으로 확인하자.

    HTML 슬라이드로 PPT를 완전히 대체할 수 있나요?

    상황에 따라 선택해야 한다. 상호작용이 필요한 미팅에는 검토할 만하지만, 기관·고객의 제출 규격이 PPTX나 PDF라면 그 형식을 충족하는 별도 산출물과 검수가 필요하다.

  • AI 앱 창업 사례, Vaultaire의 검색 유입과 수익 구조

    AI 앱 창업 사례, Vaultaire의 검색 유입과 수익 구조

    사진과 파일을 숨기는 앱은 이미 경쟁자가 많은 시장이다. Vaultaire의 AI 앱 창업 사례가 흥미로운 이유는 새로운 기능을 끝없이 붙이는 대신, 사람들이 웹에서 묻는 구체적인 질문을 유입 경로로 삼았다는 데 있다.

    Read in English

    AI Biz PT의 해설 영상과 그 바탕이 된 Starter Story 창업자 인터뷰를 함께 살펴봤다. 중심에는 세 가지가 있다. 좁은 문제를 해결하는 제품, 검색 질문에 답하는 콘텐츠, 그리고 사용자가 써본 뒤 결제할 수 있는 가격 구조다. 다만 창업자가 공개한 매출을 누구나 재현할 수 있는 수익 공식으로 읽어서는 안 된다.

    Vaultaire 사진·파일 금고 앱 소개 화면
    출처: AI Biz PT 영상 00:45, 원본 인터뷰 Starter Story. Vaultaire의 제품 포지셔닝을 보여주는 영상 장면. 현재 기능은 공식 문서로 별도 확인했다. 해설·비평 목적의 장면 인용.

    Vaultaire는 어떤 앱인가

    Vaultaire는 아이폰과 아이패드에서 사진·동영상·파일을 암호화해 보관하는 금고 앱이다. 공식 사이트는 별도의 신원 계정 없이 시작하고, 패턴으로 금고를 여는 방식을 소개한다. 무료 기능과 유료 Pro 기능을 나눠 제공한다.

    창업자 Rasty Turek는 인터뷰에서 코딩 에이전트를 활용해 첫 iOS 앱을 약 3주 만에 만들었다고 말한다. 코드와 웹사이트 문구를 직접 한 줄도 쓰지 않았다는 설명 역시 그의 발언이다. 코드 작성에 AI를 썼다는 뜻이지, 문제 선정과 검수·출시·운영까지 사람의 판단이 없었다는 뜻은 아니다.

    그는 앞서 기업 대상 사업과 여러 창업을 경험했다고 소개한다. 따라서 이 사례를 개발·사업 경험이 전혀 없는 사람이 버튼만 눌러 성공한 이야기로 바꾸면 중요한 조건이 사라진다.

    월 4만 1천 달러는 무엇을 뜻하나

    원본 인터뷰는 첫 달 매출 66달러에서 약 여섯 달 뒤 한 달 매출 4만 1천 달러로 성장한 사례로 소개한다. 창업자는 당시 일 매출을 2,000~3,000달러 수준이라고 말하고, 화면 설명에서는 약 2,000달러를 언급한다.

    여기서 숫자를 읽는 기준은 분명히 해야 한다.

    • 출처: 창업자 발언과 방송에 제시된 분석 화면이다. 회계자료나 은행 입금을 독립적으로 대조한 결과는 아니다.
    • 매출과 순이익: 영상의 금액은 애플 수수료 차감 전 매출로 안내된다. 세금·환불·개발 및 운영 비용까지 뺀 순이익이 아니다.
    • 월 매출과 MRR: 평생 이용권 판매가 포함된 한 달 매출을 월 반복매출로 볼 수 없다. 창업자도 평생 이용권 비중 때문에 MRR은 낮다고 설명한다.
    • 시점: 특정 기간의 성과다. 지금도 같은 금액을 벌고 있거나 앞으로 유지된다고 확인한 것은 아니다.

    한국어 영상 제목의 원화 금액도 환율을 적용한 환산 표현이다. 현재 환율의 실제 수령액이나 부업의 보장 수익으로 받아들이지 않는 편이 좋다.

    앱스토어의 경쟁 대신 웹의 질문을 찾았다

    창업자는 기존 사진 금고 앱들이 오래된 사용 기반과 다운로드를 갖고 있어 앱스토어 검색에서 경쟁하기 어렵다고 판단했다. 대신 제품과 연결되는 웹 검색 질문에 주목했다고 설명한다.

    예를 들어 ‘아이폰에서 사진을 안전하게 보관하는 방법’을 찾는 사람은 아직 특정 앱을 고르지 않았을 수 있다. 이런 독자에게는 기능 이름을 나열한 광고보다, 기본 기능의 범위와 대안의 차이를 설명하는 안내 글이 먼저 필요하다.

    이 사례의 요점은 경쟁자가 없는 시장을 찾았다는 것이 아니다. 경쟁자가 이미 존재하는 시장에서, 사용자가 해결책을 찾는 다른 입구를 골랐다는 데 있다.

    이를 다른 사업에 적용하려면 검색어와 제품의 거리를 먼저 봐야 한다. 방문자는 많아도 내 제품이 해결하지 못하는 질문이라면 구매까지 이어질 이유가 약하다. 반대로 조회 수가 작더라도 실제 사용자의 문제와 맞닿아 있다면 검토할 가치가 있다.

    매일 한 편보다 중요한 것은 무엇을 고치느냐다

    인터뷰에 등장하는 작업 흐름은 비교적 단순하다. Google 도구와 연결한 AI가 검색 데이터를 살펴보고, 노출되지만 방문으로 이어지지 않는 질문을 찾는다. 그 질문에 맞는 가이드를 만들고, 기존 글에서 새 글로 내부 링크를 연결한다.

    검색 질문별 안내 글과 기존 페이지 내부 링크 연결 설명
    출처: AI Biz PT 영상 04:00, 원본 인터뷰 Starter Story. 영상에서 설명하는 검색 유입·내부 링크 흐름. 실제 순위 상승을 보장하는 도표는 아니다. 해설·비평 목적의 장면 인용.

    여기서 ‘노출이 많은데 클릭이 적다’는 사실만으로 새 글부터 만들면 안 된다. 원인은 낮은 순위, 제목과 검색 의도의 불일치, 이미 있는 글의 설명 부족 등으로 나뉠 수 있다.

    실무에서는 다음 순서로 접근하는 편이 안전하다. 아래는 인터뷰 설정을 그대로 재현한 절차가 아니라, Google 공식 지표 설명을 바탕으로 정리한 적용안이다.

    1. Search Console에서 검색어와 연결 페이지를 함께 본다. 노출수·클릭수·CTR·평균 게재순위를 같은 기간과 조건으로 비교한다.
    2. 기존 글이 답할 수 있는 질문인지 확인한다. 제목과 도입부를 고치면 되는지, 별도 글이 필요한지 구분한다.
    3. 검색 결과를 직접 읽는다. 독자가 원하는 것이 방법, 비교, 가격, 오류 해결 중 무엇인지 판단한다.
    4. 직접 확인한 정보로 답을 보강한다. 제품의 실제 기능과 한계, 적용 조건을 넣는다.
    5. 관련 글에서 자연스럽게 연결한다. 방문자가 다음 단계로 이동할 이유가 있는 위치에 내부 링크와 제품 안내를 둔다.
    6. 수정 이력을 남기고 같은 조건으로 관찰한다. 검색 클릭과 제품 이동, 설치와 구매를 서로 다른 단계로 측정한다.

    Search Console은 내 사이트의 검색 실적을 보는 도구다. 키워드 플래너는 광고용 키워드 조사 도구로, 같은 데이터가 아니다. 인터뷰의 도구 연결 설명을 자신의 Search Console 실적과 광고 키워드 자료가 자동으로 동일하다는 뜻으로 읽으면 안 된다.

    또한 검색 지표의 CTR과 웹사이트에서 앱스토어로 이동하는 비율, 다운로드 이후 결제 전환율은 각각 분모가 다르다. 하나의 ‘전환율’로 묶으면 어느 단계가 개선됐는지 알기 어렵다.

    하루 한 편은 Google의 순위 공식이 아니다

    창업자는 하루 한 편씩 가이드를 발행하고, Google이 새 글을 알아보는 데 약 3~4일이 걸렸다고 설명한다. 이는 해당 사이트에 관한 경험담이지, 다른 사이트에도 적용되는 색인 시간 보장은 아니다.

    ‘하루 한 편이라서 Google이 좋아한다’는 해석도 공식 규칙으로 옮길 수 없다. Google은 생성형 AI 사용 자체보다 정확성·품질·관련성·사용자에게 더하는 가치를 강조한다. 가치를 더하지 않고 페이지를 대량 생성하면 스팸 정책 위반에 해당할 수 있다고 안내한다.

    중요한 선택은 발행량의 많고 적음이 아니다. 이미 있는 설명을 바꿔 쓴 글인지, 독자의 질문에 더 나은 답을 제공하는 글인지가 먼저다. AI는 초안과 데이터 정리에 쓸 수 있지만, 실제 사용 경험이나 제품 검증을 대신 만들어낼 수는 없다.

    첫날 결제율만으로 판단하지 않은 가격 구조

    영상에는 다운로드 대비 결제 지표로 DAY 1의 5.47%, DAY 35의 8.62%가 제시된다. 창업자는 처음에 결제하지 않아도 사용하면서 구매하는 사람이 늘어난다고 설명한다.

    영상 속 DAY 35 다운로드 대비 결제 전환율 8.62퍼센트 화면
    출처: AI Biz PT 영상 05:27, 원본 인터뷰 Starter Story. 영상 속 DAY 35 지표. 지표의 분모와 관찰 조건을 확인하지 않은 독립 성과 검증은 아니다. 해설·비평 목적의 장면 인용.

    다만 이 화면만으로 신뢰가 높아져 결제가 늘었다는 인과관계를 입증할 수는 없다. 관찰 기간이 길어지면 누적 결제 비율이 오를 수 있다. 동일 코호트인지, 분모와 지표 정의가 무엇인지도 확인해야 한다.

    그럼에도 실무적으로 검토할 질문은 남는다. 내 제품이 첫 사용 순간에 가치를 판단할 수 있는가, 아니면 보관·기록·업무처럼 일정 기간 사용한 뒤 가치를 느끼는가. 이 차이에 따라 첫 화면의 결제 요청과 무료 범위를 다르게 설계할 수 있다.

    영상 당시 제시된 가격은 주간 1.99달러, 연간 19.99달러, 평생 이용권 39.99달러다. 현재 한국 앱스토어의 판매 가격을 확인한 표가 아니므로 구매 판단에는 앱 안의 최신 조건을 확인해야 한다.

    영상 속 Vaultaire 주간 연간 평생 이용권 가격 비교
    출처: AI Biz PT 영상 05:37, 원본 인터뷰 Starter Story. 촬영 당시 제시된 달러 가격. 현재 국가별 앱스토어 가격과 다를 수 있다. 해설·비평 목적의 장면 인용.

    창업자는 구매자의 약 60%가 평생 이용권을 선택하고, 매출 기여는 80%를 넘는다고 추정한다. 이는 정확한 정산 명세를 대조한 비중이 아니라 인터뷰의 설명이다.

    평생 이용권은 초기 현금 유입에 유리할 수 있다. 하지만 미래의 업데이트·고객 지원 의무도 함께 남는다. 서버 비용이 적다는 이유만으로 장기 비용이 사라지거나, 모든 앱에 같은 가격이 맞는 것은 아니다.

    영상의 보안 설명은 공식 문서와 구분해서 읽자

    사업 사례를 다룰 때도 제품 약속은 정확해야 한다. Vaultaire 공식 사이트와 개인정보처리방침을 확인하면, 영상의 짧은 설명을 보충해야 할 부분이 나온다.

    • 로컬 암호화와 외부 서비스 부재는 다르다. 공식 안내에는 기기에서 암호화한 뒤 CloudKit에 저장하는 iCloud 백업이 있다. 백업은 기본 활성화이며 끌 수 있다고 설명한다.
    • 패턴 분실이 곧바로 복구 불가를 뜻하지 않는다. 공식 FAQ는 복구 문구를 안내한다. 패턴과 복구 문구를 모두 잃으면 개발자가 데이터를 복구해주지 못한다는 설명이다.
    • 신원 계정이 없다고 분석 데이터까지 없는 것은 아니다. 앱 사용 분석과 오류 진단은 기본 활성화이며 설정에서 끌 수 있다고 명시한다. 웹사이트 분석도 별도로 설명한다.
    • 암호화가 모든 상황의 안전을 보장하지는 않는다. 공식 보안 문서도 잠금 해제된 기기, 운영체제와 앱 구현을 신뢰 경계에 포함한다.

    개인정보처리방침에는 광고 귀속 측정 경로도 설명돼 있다. 이는 실제 광고 지출액을 입증하지는 않는다. 다만 인터뷰의 ‘광고 없이 성장했다’는 경험담을 영구적인 무광고 운영 정책으로 확대할 근거도 없다.

    FBI가 도움을 요청했다는 이야기는 창업자의 일화다. 별도 확인한 수사 기록이나 독립 보안 감사 결과가 아니므로, 그 자체를 보안 성능의 증명으로 사용하지 않았다. 이 글도 앱을 설치해 암호화 구현이나 복구 기능을 독립 시험한 리뷰는 아니다.

    내 사업에 가져올 것은 자동 발행보다 운영의 연결이다

    Vaultaire 사례에서 가져올 만한 것은 ‘AI가 알아서 돈을 번다’는 결론이 아니다. 사용자의 문제, 검색 질문, 제품 소개, 가격, 측정을 한 흐름으로 연결했다는 점이다.

    시작은 작아도 된다. 내 사이트에 이미 노출되는 질문 하나를 고르고, 기존 설명이 충분한지 확인해 보자. 새 글이 필요하다면 실제 기능과 한계를 확인한 뒤 발행한다. 제품으로 이동하는 안내도 독자가 다음 행동을 할 이유가 있는 곳에 둔다.

    AI에게 맡길 범위는 데이터 정리와 개선 후보 제안부터 시작할 수 있다. 공개 발행과 가격·보안 약속의 변경은 검토 대상으로 남겨두는 편이 좋다. 성공 사례를 따라 할 때도 숫자보다 먼저 복제해야 할 것은 이런 판단과 검증의 순서다.

    함께 읽으면 좋은 글

    참고자료

    본문 이미지는 AI Biz PT 영상의 설명 장면을 해설·비평 목적으로 인용했다. 원본 인터뷰는 Starter Story에 있다. 매출·가격·전환 지표는 영상 당시 자료이며, 제품 기능과 정책은 2026년 10월 30일 확인한 공식 안내를 기준으로 구분했다.

    FAQ

    Vaultaire는 AI로 만든 앱이라고 볼 수 있나요?

    창업자는 코딩 에이전트를 활용했고 코드와 웹 문구를 직접 쓰지 않았다고 설명한다. 다만 그 발언이 무인 개발이나 무검수 운영을 뜻하지는 않는다. 제품 판단과 운영 책임은 별개다.

    월 4만 1천 달러가 반복매출이나 순이익인가요?

    아니다. 영상은 특정 한 달의 매출을 소개한다. 평생 이용권 판매가 포함돼 MRR과 다르며, 수수료·비용·세금을 공제한 순이익도 아니다. 회계자료로 독립 검증한 수치도 아니다.

    AI로 매일 글 한 편을 쓰면 검색 순위가 오르나요?

    보장되지 않는다. 하루 한 편은 창업자의 운영 방식일 뿐이다. 검색 의도와 제품의 연결, 정확성, 정보 가치, 기존 글과의 차별성을 먼저 점검해야 한다.

    Vaultaire는 외부 서비스도 없고 데이터를 전혀 수집하지 않나요?

    그렇게 단정하면 안 된다. 공식 안내에는 암호화된 CloudKit 백업·공유와 기본 활성화 분석·오류 진단이 있다. 읽을 수 있는 금고 내용을 개발자가 보유하지 않는다는 설명과, 외부 서비스·분석 데이터가 전혀 없다는 주장은 다르다.

  • 2026년 11월 대한민국 축제 일정|불꽃·국화·먹거리 모음

    11월에는 국화가 남아 있는 공원부터 불꽃이 펼쳐지는 바닷가, 제철 먹거리를 만나는 장터까지 여행의 선택지가 넓어진다. 다만 같은 ‘11월 축제’라도 첫날에 끝나는 행사와 마지막 주말에 시작하는 행사는 여행 계획이 전혀 다르다.

    Read in English

    2026년 11월 대한민국 축제 일정을 날짜와 지역별로 정리했다. 한국관광공사와 지자체·공식 관광기관의 안내에서 올해 일정을 확인한 주요 14곳이다. 전국의 모든 행사를 나열한 목록은 아니며, 10월에 시작해 11월까지 이어지는 축제도 포함했다.

    2026년 11월 축제 일정 한눈에 보기

    아래 날짜는 모두 2026년 기준이다. 축제 이름을 누르면 해당 공식 안내로 이동한다. 행사 기간 전체에 모든 공연·체험이 매일 운영되는 것은 아니므로, 원하는 프로그램의 날짜도 함께 확인하자.

    축제 전체 행사 기간 지역 주요 장소 관람 포인트
    노원달빛산책 10.16~11.08 서울 노원 당현천 일원 빛 조각·야간 공공미술
    익산천만송이 국화축제 10.23~11.01 전북 익산 중앙체육공원 일원 국화 조형물·야간경관
    대한민국 국향대전 10.23~11.08 함평 함평엑스포공원 대형 국화 작품·분재·체험
    부여국화축제 10.30~11.08 충남 부여 궁남지 일원 백제 문화를 담은 국화 작품
    마산가고파국화축제 10.31~11.08 경남 창원 3·15해양누리공원·합포수변공원·해양신도시 일원 바다와 국화·문화공연
    청송사과축제 11.04~11.08 경북 청송 청송읍 월막리 용전천 일원 사과 체험·농특산물 판매
    괴산김장축제 11.05~11.08 충북 괴산 유기농엑스포광장·종합운동장 일원 김장 체험·김치마켓
    제주올레걷기축제 11.05~11.07 제주 제주올레 19·20코스 일대 걷기·마을 문화·공연
    구미라면축제 11.06~11.08 경북 구미 구미역·역전로 등 원도심 다양한 라면 요리·체험
    김해분청도자기축제 11.06~11.10 경남 김해 롯데가든파크 분청도자 전시·판매·제작 체험
    부산불꽃축제 11.07 부산 광안리해수욕장·광안대교 일대 해상 멀티미디어 불꽃쇼
    고흥유자축제 11.12~11.15 고흥 풍양면 한동리 유자축제장 일원 유자 체험·유자밭·빛정원
    포항국제불빛축제 11.19~11.21 경북 포항 영일대해수욕장 국제불꽃쇼·야간 문화행사
    파주장단콩축제 11.27~11.29 경기 파주 임진각 광장 장단콩·농특산물·먹거리

    익산 국화축제는 11월 1일이 마지막 날이다. 국화축제를 여유 있게 고르고 싶다면 11월 8일까지 이어지는 부여·함평·마산 행사도 함께 비교해 보자.

    주말 일정부터 정한다면 이렇게 고르자

    • 11월 1일: 익산 국화축제의 마지막 날을 포함해, 10월부터 이어진 가을 행사를 살펴보기 좋다.
    • 11월 7~8일: 부산불꽃축제, 청송사과축제, 구미라면축제, 괴산김장축제 등 선택지가 많다. 부산불꽃축제는 7일 하루 행사라는 점에 주의하자.
    • 11월 14~15일: 고흥유자축제를 중심으로 남도 여행을 계획할 수 있다.
    • 11월 21~22일: 포항국제불빛축제는 21일에 끝난다. 일요일인 22일에도 이어진다고 생각하고 예약하지 않도록 주의하자.
    • 11월 28~29일: 파주장단콩축제가 열리는 마지막 주말이다. 수도권에서 지역 먹거리와 장터를 찾는 일정으로 검토할 만하다.

    걷기 여행을 원한다면 제주올레걷기축제의 11월 5~7일 일정도 별도로 살펴보자. 토요일까지 이어지는 행사여서 금요일을 포함한 여행 계획과 연결할 수 있다.

    불꽃과 야경을 보고 싶다면: 부산·포항·노원

    부산불꽃축제: 11월 7일, 광안리의 밤

    부산불꽃축제는 광안리해수욕장과 광안대교를 배경으로 음악·조명·불꽃을 결합하는 행사다. 공식 안내에는 해외초청불꽃쇼와 부산멀티불꽃쇼가 주요 프로그램으로 소개돼 있다.

    유료 관람석을 이용할 계획이라면 좌석 종류와 예매 현황을 먼저 확인하는 것이 좋다. 한국관광공사 안내의 정규 티켓은 R석 10만 원, S석 7만 원이다. 이는 유료 좌석 안내이며, 현재 잔여석이나 현장 구매 가능 여부를 뜻하지는 않는다.

    방문 전에는 부산불꽃축제 공식 홈페이지에서 당일 일정과 교통통제·관람 안내를 확인하자. 특정 장소에 도착하면 반드시 좋은 시야를 확보할 수 있다고 생각하고 일정을 짜는 것은 피하는 편이 좋다.

    포항국제불빛축제: 11월 19~21일, 영일대의 불과 빛

    포항국제불빛축제는 영일대해수욕장에서 열린다. 한국관광공사 안내는 국제불꽃쇼, 미디어파사드, 나이트카니발과 공연 등을 주요 콘텐츠로 소개한다.

    축제의 전체 기간과 메인 불꽃쇼의 시간표는 구분해서 확인해야 한다. 3일 동안 같은 규모의 불꽃쇼가 계속된다는 뜻은 아니다. 관람을 원하는 날의 프로그램을 확인한 뒤 숙소와 이동편을 정하자.

    노원달빛산책: 11월 8일까지, 당현천을 따라 걷는 빛 전시

    장거리 여행보다 서울에서 저녁 산책을 하고 싶다면 노원달빛산책을 살펴볼 만하다. 당현천 일원의 등·빛 조각 작품과 공공미술을 중심으로 하는 야간 축제다.

    관람료는 무료로 안내된다. 다만 전시를 보는 시간과 주말 공연·해설 프로그램의 운영 시간은 다를 수 있으므로, 특정 프로그램을 원한다면 일정을 별도로 확인하자.

    국화축제는 11월 초가 중요하다

    익산천만송이 국화축제: 11월 1일까지

    익산은 국화 정원과 대형 조형물, 국화분재 전시와 야간경관을 함께 소개한다. 올해 안내의 관람료는 무료다. 다만 11월 여행으로 잡을 수 있는 날은 행사 마지막 날인 1일이라는 점을 먼저 기억하자.

    부여국화축제: 궁남지에서 만나는 백제와 국화

    부여국화축제는 궁남지 일원에서 열린다. 금동대향로·사비문 등 백제의 역사와 문화를 담은 국화 조형물을 관람하는 것이 특징이다. 무료로 안내되며, 체험이나 먹거리 이용 비용까지 모두 무료라는 뜻은 아니다.

    대한민국 국향대전: 함평의 대형 국화 작품과 체험

    함평의 대한민국 국향대전은 국화 기획작품과 분재, 공연·체험을 함께 살펴볼 수 있는 행사다. 다른 국화축제와 달리 입장료가 있으므로 예산을 나눠 잡는 편이 좋다.

    한국관광공사 안내의 개인 성인 현장 입장료는 7,000원이다. 사전예매 할인 기간은 10월 22일까지로 안내돼 있으므로, 11월 방문자가 이미 끝난 할인 가격을 현재 구매 가능한 가격으로 생각하지 않도록 주의하자. 연령·단체·무료입장 조건은 공식 안내에서 확인할 수 있다.

    마산가고파국화축제: 바다와 국화를 함께 보는 일정

    마산가고파국화축제는 3·15해양누리공원, 합포수변공원, 해양신도시 일원에서 열린다. 국화 전시와 문화공연을 함께 소개하며 관람료는 무료로 안내된다.

    행사장이 여러 공간으로 나뉘어 있으므로 보고 싶은 전시와 공연의 위치를 먼저 확인하자. 축제 기간 전체를 불꽃쇼나 낙화놀이의 상시 운영 기간으로 받아들여서는 안 된다.

    제철 먹거리와 체험을 찾는다면

    청송사과축제와 구미라면축제

    청송사과축제는 11월 4~8일 열린다. 사과·농특산물 판매뿐 아니라 사과를 소재로 한 체험과 참여 프로그램이 소개돼 있다. 입장은 무료이며 일부 체험은 유료다.

    구미라면축제는 11월 6~8일 구미역과 역전로 등 원도심에서 열린다. 다양한 라면 요리와 갓 튀긴 라면, 만들기 체험 등을 살펴볼 수 있다. 축제 입장은 무료로 안내되지만 음식 구매 비용은 별도다.

    특히 구미라면축제의 관광공사 페이지는 일부 먹거리 정보를 전년도인 2025년 자료라고 표시하고 있다. 예전 메뉴판의 가격을 올해 판매 가격으로 받아들이지 말고, 2026년 공식 안내와 현장 메뉴판을 기준으로 고르자.

    괴산김장축제: 구경과 김장 체험은 다르게 준비한다

    괴산김장축제는 11월 5~8일 유기농엑스포광장과 종합운동장 일원에서 열린다. 원스톱·드라이브스루 김장 등 사전예약형 체험과 김치마켓, 현장 참여 프로그램을 구분해서 살펴보는 것이 좋다.

    공식 홈페이지는 예약 없이 참여하는 즉석 김장 프로그램도 소개한다. 그렇다고 모든 김장 프로그램을 예약 없이 이용할 수 있다는 뜻은 아니다. 원하는 방식의 접수 여부·물량·참가비를 먼저 확인하자. 드라이브스루 김장은 올해 종합운동장으로 장소를 옮겼다는 군청 안내도 참고할 만하다.

    고흥유자축제: 11월 12~15일, 유자밭과 함께하는 여행

    고흥유자축제는 풍양면 한동리 일원에서 열린다. 유자청 만들기 등 유자를 활용한 체험과 직거래장터, 유자밭 탐방로·야간 빛정원 등을 주요 내용으로 소개한다.

    기본 관람은 무료로 안내되지만 일부 체험과 프로그램은 유료다. 유자 수확처럼 참여 인원과 운영 시간이 정해질 수 있는 체험은 현장 상황을 따로 확인하는 편이 좋다.

    파주장단콩축제: 11월 마지막 주말의 장터

    파주시 공식 안내에서 확인한 올해 일정은 11월 27~29일, 장소는 임진각 광장이다. 다른 해의 날짜나 비공식 글의 일정을 그대로 가져오지 않도록 주의하자.

    장단콩과 농특산물, 먹거리 등을 살펴보는 여행으로 계획할 수 있다. 공식 페이지에도 과거 연도의 판매가격 표가 함께 있으므로, 구입 비용은 올해 안내를 기준으로 확인하는 것이 좋다.

    걷기와 만들기 체험: 제주올레·김해 분청도자기

    제주올레걷기축제: 11월 5~7일, 19·20코스

    제주관광공사 비짓제주는 올해 축제를 제주올레 19·20코스에서 진행하는 걷기 행사로 안내한다. 공연과 전시·체험, 마을 먹거리 등을 길 위에서 함께 만나는 방식이다.

    안내 참가비는 일반 3만 원이며 할인 조건은 별도로 제시돼 있다. 다만 비짓제주에 표시된 사전신청 기간은 10월 9일까지다. 지금 참가하려면 추가 접수나 참여 가능 범위를 주최 측에 확인해야 한다. 항공권부터 예약한 뒤 현장에서 모든 프로그램에 참여할 수 있다고 가정하지 않는 편이 좋다.

    김해분청도자기축제: 11월 6~10일, 롯데가든파크

    김해분청도자기축제는 분청도자 전시·판매와 물레·머그컵 꾸미기 등 제작 체험을 소개한다. 올해 관광공사 안내의 장소는 김해 롯데가든파크다. 예전 행사 후기의 장소를 그대로 목적지로 입력하지 않도록 하자.

    체험마다 운영 방식과 비용이 다를 수 있으므로, 원하는 프로그램의 접수 방법을 확인하는 것이 좋다. 안내 페이지의 도자기 판매 할인과 행사 입장·체험비는 같은 항목으로 취급하지 말아야 한다.

    출발 전에는 이 네 가지를 다시 확인하자

    1. 올해 날짜와 세부 시간표: 축제 기간, 메인 공연, 체험 접수 시간을 따로 확인한다.
    2. 입장료와 추가 비용: 입장 무료라도 음식·재료·유료 좌석·주차 비용은 별도일 수 있다.
    3. 날씨와 행사 변경 공지: 불꽃과 야외 전시는 기상 여건에 따라 운영이 달라질 수 있다. 출발 당일 공지까지 살펴보자.
    4. 교통과 귀가편: 공식 교통통제·셔틀·주차 안내와 마지막 이동편을 확인한다. 과거 후기의 동선을 그대로 따르지 않는다.

    축제 달력에 긴 기간이 표시돼 있어도 핵심 행사가 그 기간 내내 반복되는 것은 아니다. 예를 들어 한국관광공사에 등록된 운정호수공원 행사는 불꽃쇼와 이후 불빛정원의 운영 기간이 함께 제시돼 있다. 11월에도 매일 불꽃쇼가 열린다는 뜻으로 읽으면 안 된다.

    함께 읽으면 좋은 여행 글

    참고자료와 확인 기준

    표의 축제 이름에는 해당 공식 안내 링크를 연결했다. 한국관광공사의 축제 소개는 운영기관이 제출한 자료를 바탕으로 제공되며, 지자체와 공식 관광기관의 올해 안내도 함께 확인했다.

    일정·장소·요금은 2026년 10월 28일 확인 기준이다. 주최 측 사정이나 날씨에 따라 변경될 수 있으므로 예약·결제 전과 출발 당일 공식 공지를 다시 확인하자.

    FAQ

    11월에 시작하지 않은 축제도 포함돼 있나요?

    그렇다. 10월에 시작했어도 11월에 관람 가능한 날짜가 있으면 포함했다. 표에는 전체 행사 기간을 표시했으며, 익산 국화축제처럼 11월 1일에 끝나는 행사도 구분했다.

    11월 축제는 모두 무료인가요?

    아니다. 국향대전은 입장료가 있고 부산불꽃축제에는 유료 관람석이 있다. 입장이 무료인 행사도 음식·체험·재료 비용은 별도일 수 있다. 걷기·김장 프로그램은 신청 조건과 참가비까지 확인해야 한다.

    포항국제불빛축제와 파주장단콩축제는 언제인가요?

    공식 안내에서 확인한 2026년 일정은 포항국제불빛축제 11월 19~21일, 파주장단콩축제 11월 27~29일이다. 메인 공연과 체험의 세부 시간은 해당 주최 측 안내에서 다시 확인하자.

    방문 직전에는 어디에서 변경 여부를 확인하나요?

    표의 축제 이름에 연결한 공식 안내와 축제·지자체 홈페이지를 먼저 확인하면 된다. 기상 변화와 교통통제, 유료 좌석·체험 접수 상황은 출발 전 최신 공지를 기준으로 판단하는 것이 좋다.